
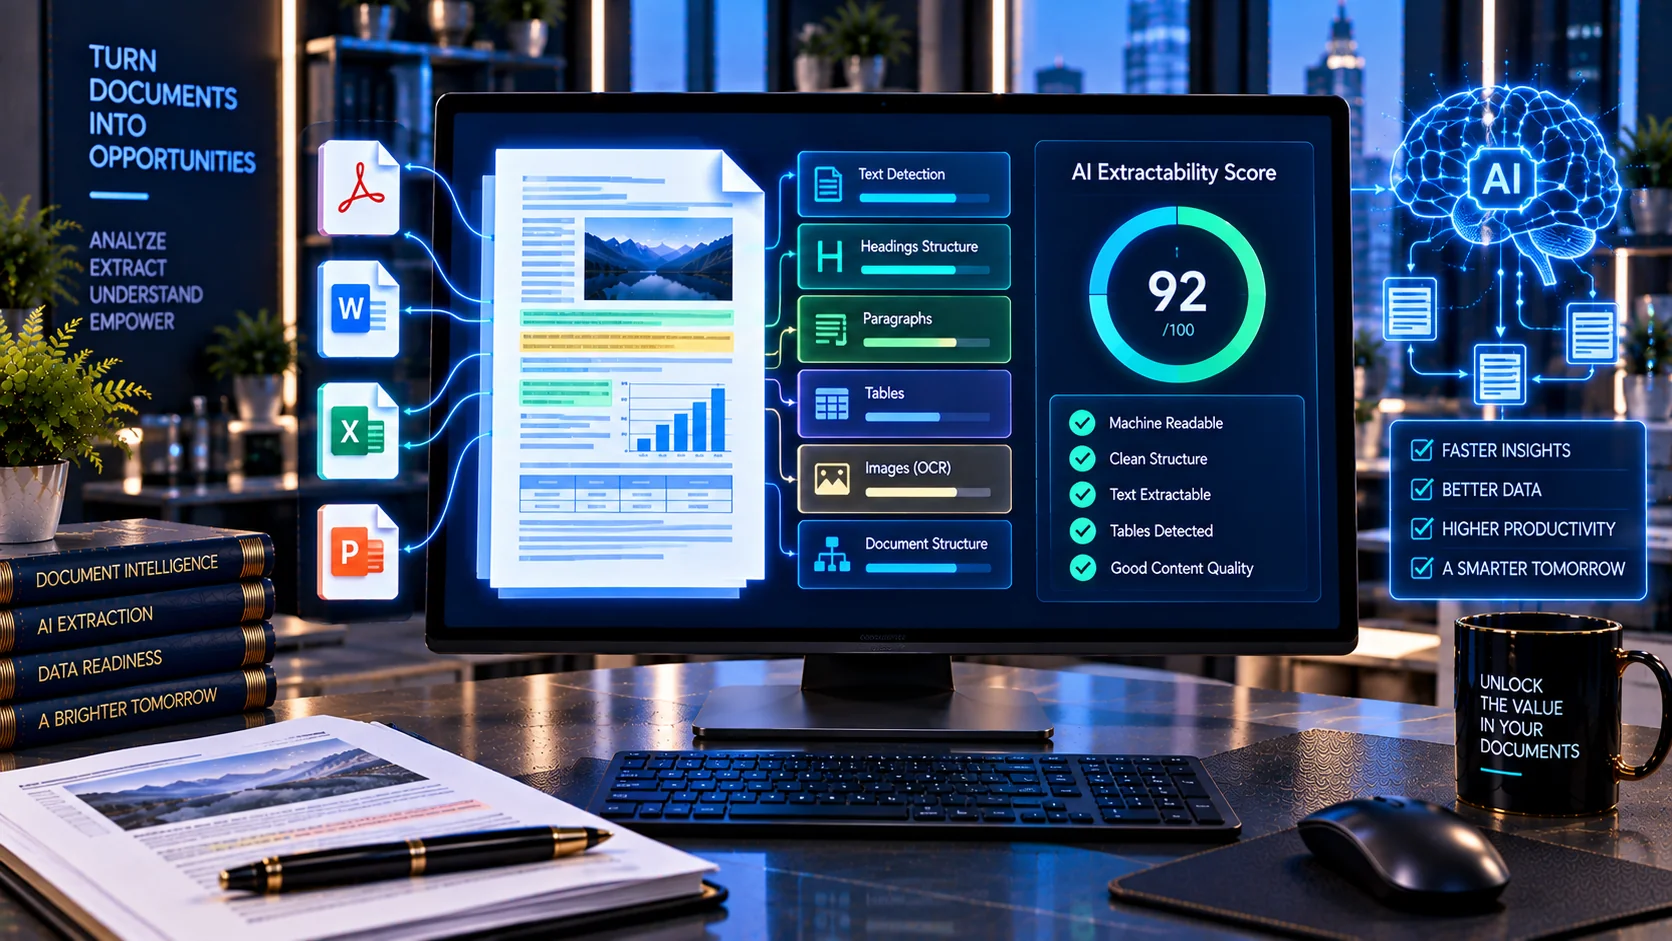
A document can be visually readable to a person while still being difficult for software and AI systems to extract, parse, search, or retrieve accurately. The AI Document Extractability Score evaluates important document characteristics such as text availability, structure, readability, content cleanliness, and machine-readable formatting to provide a practical diagnostic score before a document is used in AI, RAG, search, or automated processing workflows.
AI Document Extractability Score
Assess whether a document contains enough usable text, structure, and machine-readable content for downstream AI processing. The analysis is heuristic and runs locally in your browser.
This score is a deterministic heuristic, not a guarantee of AI retrieval, citation, model understanding, or document correctness.
What Is an AI Document Extractability Score?
An AI Document Extractability Score is a diagnostic measurement that evaluates how easily useful information can be extracted from a document in a machine-readable form.
A document with clear text, consistent structure, meaningful headings, readable paragraphs, and clean content is generally easier for document-processing systems to parse than a document dominated by images, fragmented text, broken characters, or poorly structured content.
Modern AI document-processing systems distinguish between machine-readable text and richer document structure. For example, Google Cloud’s document parsing systems can identify text blocks, headings, paragraphs, tables, lists, and other structural elements for search and answer-generation workflows.
The PKCapra AI Document Extractability Score brings several observable document-quality signals together into one practical diagnostic.
Why Document Extractability Matters for AI
AI systems do not necessarily consume a document in exactly the same way a human reads it.
A document may contain valuable information but still create extraction challenges because of:
- Missing text
- Image-only pages
- Poor OCR
- Broken characters
- Extremely long lines
- Fragmented text
- Weak document structure
- Inconsistent headings
- Excessive duplication
- Unusual control characters
- Poor paragraph boundaries
- Machine-unfriendly formatting
These issues can affect downstream workflows such as:
- AI summarization
- RAG
- Semantic search
- Question answering
- Information extraction
- Document classification
- Knowledge-base creation
- Automated document processing
Document parsing and layout extraction are particularly relevant to RAG systems because parsers can use headings, paragraphs, tables, lists, and other structural elements to organize content into useful units.
How the AI Document Extractability Score Works
PKCapra analyzes the document and evaluates several observable characteristics.
The checker can assess:
- Text availability
- Character and word counts
- Paragraph structure
- Line structure
- Heading signals
- List signals
- Average paragraph size
- Average line length
- Long-line patterns
- Fragmented text
- Repeated content
- Replacement characters
- Control characters
- Machine-readable text characteristics
- Overall document cleanliness
These signals are combined into separate diagnostic dimensions and an overall extractability score.
The Four Main Extractability Dimensions
The tool evaluates four practical areas:
Text Availability
This measures whether the document contains enough accessible text for meaningful extraction.
A document with a strong text layer is generally easier to process than a scanned or image-only document with little machine-readable content.
Text availability can be affected by:
- Scanned pages
- Image-based PDFs
- Missing text layers
- Broken extraction
- Empty pages
- Poor OCR
If the main problem is OCR quality, use the AI OCR Quality Checker for a more focused analysis.
Structure
Document structure helps software identify relationships between pieces of information.
Useful structural signals can include:
- Headings
- Subheadings
- Paragraphs
- Lists
- Sections
- Consistent content boundaries
Google’s document parsing documentation specifically describes extracting structural elements such as titles, headings, paragraphs, tables, lists, headers, and footnotes for document search and RAG workflows.
Machine Readability
Machine readability refers to how cleanly the available content can be interpreted by software.
Potential problems include:
- Garbled characters
- Replacement characters
- Unexpected control characters
- Broken text
- Excessive fragmentation
- Unusual encoding artifacts
A document does not need to be perfectly formatted to be machine-readable, but severe extraction problems can reduce the usefulness of automated processing.
Content Cleanliness
Clean content contains fewer unnecessary or repeated elements that can interfere with downstream processing.
Examples include:
- Repeated paragraphs
- Duplicate headers
- Repeated footer content
- Excessive fragments
- Broken lines
- Unusual character sequences
Content cleanliness is particularly useful when preparing documents for indexing, chunking, and retrieval.
Understanding the Extractability Score
The tool produces an overall score out of 100 based on the signals detected during analysis.
The score is designed as a diagnostic indicator, not as a universal measure of AI understanding.
A higher score generally means that fewer structural and machine-readability problems were detected.
A lower score indicates that the document may benefit from cleanup, OCR improvement, structural correction, or additional preparation before entering an AI workflow.
The score should therefore be treated as an actionable diagnostic rather than a guarantee that an AI model will understand, retrieve, or cite the document.
Does a High Extractability Score Guarantee AI Citations?
No.
Extractability and AI citation are related concepts, but they are not the same thing.
A document or web page can be technically accessible and structurally clean while still not being selected by an AI system.
Current research and industry guidance distinguish extractability from ranking or citation guarantees. Extractability describes how easily information can be isolated and reused; it does not guarantee that a particular AI system will retrieve or cite it.
PKCapra’s score should therefore be used to identify document-quality improvements rather than predict AI citation outcomes.
Document Extractability for RAG
RAG systems depend on retrieving useful pieces of information from a larger knowledge base.
If a source document has poor extraction characteristics, problems can appear before retrieval even begins.
For example:
Original document → extraction → chunking → indexing → retrieval → AI response
If extraction produces incomplete or corrupted content, later stages may work with incomplete information.
Google’s document-processing documentation explains that parsing and layout detection can support content-aware chunking and improve search and answer generation for structured documents.
This makes document extractability an important preparation step for RAG workflows.
Extractability and Document Structure
Good document structure makes it easier to identify the boundaries between different concepts.
Consider a document with:
- Clear headings
- Shorter logical paragraphs
- Proper lists
- Consistent sections
- Meaningful labels
Compared with a document containing:
- Huge blocks of text
- Random line breaks
- Repeated headers
- Broken paragraphs
- Missing headings
The first structure generally provides clearer boundaries for parsing and chunking.
For detailed structural analysis, use the Document Structure Analyzer for AI.
Extractability and Headings
Headings can provide important structural signals.
A document with meaningful headings can make it easier to identify topics and relationships between sections.
For example:
Poor structure
Product information…
More information…
Details…
Clear structure
Product Specifications
Compatibility
Installation Requirements
Maintenance Instructions
The second structure provides clearer semantic boundaries for both humans and document-processing systems.
Extractability and Paragraph Length
Paragraph length can influence how content is divided and processed.
Extremely long paragraphs may contain several unrelated concepts, while extremely short fragments can lose context.
The tool therefore examines paragraph characteristics as part of the broader extractability assessment.
The goal is not to enforce one universal paragraph length. Different document types naturally require different structures.
Instead, the checker identifies unusual patterns that may deserve review.
Extractability and Long Lines
Very long lines can sometimes indicate:
- Broken PDF extraction
- Missing paragraph boundaries
- OCR problems
- Flattened document structure
- Improper text conversion
- Poorly formatted source content
A long line is not automatically an error. Technical documents, code, URLs, tables, and other content may legitimately contain long lines.
The checker treats long-line patterns as diagnostic signals rather than automatic failures.
Extractability and Duplicate Content
Duplicate content can increase unnecessary text volume and potentially distort downstream processing.
Common examples include:
- Repeated headers
- Repeated footers
- Duplicate page text
- Repeated navigation content
- Copy-and-paste duplication
The checker can identify repeated-content patterns that may deserve cleanup before indexing or chunking.
For broader RAG preparation, use the RAG Document Readiness Checker.
Extractability and OCR
OCR quality can directly affect extractability.
A scanned PDF may contain visually readable information but little usable machine-readable text.
Even when OCR has been applied, recognition errors can produce:
- Missing words
- Incorrect characters
- Broken sentences
- Strange symbols
- Incorrect numbers
- Fragmented text
The AI OCR Quality Checker can be used alongside the extractability score to investigate OCR-specific problems.
Extractability and PDF Documents
PDF files can contain several different types of content:
- Native digital text
- Scanned images
- OCR text layers
- Tables
- Graphics
- Forms
- Embedded objects
Two PDFs that look almost identical visually can behave very differently when processed by software.
The AI-Ready PDF Checker provides a more PDF-specific assessment covering text availability, document structure, OCR characteristics, metadata, and other machine-readability signals.
Extractability and DOCX Documents
DOCX files generally preserve more structural information than many flattened document formats.
Depending on how the document was created, a DOCX can contain:
- Headings
- Paragraphs
- Lists
- Tables
- Hyperlinks
- Headers
- Footers
- Metadata
- Embedded content
The AI-Ready DOCX Checker can provide a more focused assessment of DOCX structure and AI-readiness.
Extractability for AI Search
AI search systems need to retrieve useful information from available content before that information can potentially contribute to an answer.
Clear structure can make information easier to parse and isolate.
However, extractability is only one part of a broader AI-search process. Crawl access, relevance, authority, source quality, and system-specific retrieval behavior can also affect whether content is used.
The AI Search Readiness Analyzer can be used when the focus is website-level AI search readiness rather than document-level extractability.
Extractability vs. AI Search Readiness
These concepts should not be confused.
AI Document Extractability Score focuses on a specific document and asks:
How cleanly and completely can useful information be extracted from this document?
AI Search Readiness is broader and can involve website accessibility, content structure, search-oriented signals, and other factors.
A document can have strong extractability while the website hosting it has unrelated search-access issues.
Likewise, a highly accessible website can contain individual documents with poor extraction quality.
Extractability vs. OCR Quality
OCR quality and document extractability overlap, but they measure different things.
OCR Quality focuses on whether OCR-generated text contains signs of recognition problems.
Document Extractability evaluates the broader machine-readable quality of the document, including text availability, structure, cleanliness, and formatting.
For scanned documents, both checks can be useful.
Extractability vs. RAG Readiness
RAG readiness is broader than extractability.
A document can have good extractability but still require:
- Better chunking
- Duplicate removal
- Metadata cleanup
- Prompt-injection scanning
- PII detection
- Link inspection
Use the RAG Chunking Analyzer to compare chunking approaches and the Document Chunking Calculator to estimate chunk counts and token requirements.
How to Improve Document Extractability
If a document receives a weak extractability assessment, consider the following workflow:
- Make sure the document contains usable machine-readable text.
- Run OCR on scanned pages when necessary.
- Remove obvious duplicated content.
- Repair garbled or corrupted characters.
- Improve heading and section structure.
- Break large text blocks into logical paragraphs.
- Remove unnecessary boilerplate.
- Check for unexpected control characters.
- Review tables and complex layouts.
- Re-check the document after cleanup.
The objective is not to make every document identical. The objective is to make important information easier for machines to identify and process.
AI Document Preparation Workflow
A practical PKCapra workflow can combine several specialized checks:
Step 1 — Extractability
Run the AI Document Extractability Score.
Step 2 — OCR
If the document is scanned or shows suspicious text patterns, run the AI OCR Quality Checker.
Step 3 — Structure
Use the Document Structure Analyzer for AI.
Step 4 — Safety
Run the AI Document Safety Scanner and AI Prompt Injection Document Scanner.
Step 5 — Privacy
Check metadata and sensitive information before sharing or submitting the document.
Step 6 — RAG Preparation
Run the RAG Document Readiness Checker, then analyze chunking and token requirements.
This creates a layered workflow instead of relying on one generalized document score.
What the AI Document Extractability Score Does Not Do
The tool does not claim to predict the exact behavior of a specific AI model.
It does not guarantee:
- AI citations
- Search rankings
- Retrieval success
- Perfect summarization
- Perfect extraction
- Correct answers from every AI system
It also does not replace professional document review for legal, financial, medical, compliance, or other high-stakes workflows.
The score is intended to help identify observable document-quality issues that can be improved before downstream AI processing.
Browser-Based Document Analysis
PKCapra’s AI Document Extractability Score is designed for browser-side analysis.
The tool is intended to evaluate document content without requiring a remote AI API simply to calculate its diagnostic results.
This can be useful when working with:
- Business documents
- Internal reports
- Research material
- Contracts
- Knowledge-base documents
- Client files
- AI-ready document collections
Always follow your organization’s privacy and security requirements when handling confidential documents.
When Should You Use the AI Document Extractability Score?
Use the checker before:
- Uploading documents to AI systems
- Creating a RAG knowledge base
- Indexing document collections
- Building semantic search systems
- Processing large document archives
- Converting scanned files into AI-readable content
- Running automated document extraction
- Creating AI-powered knowledge bases
- Preparing documents for enterprise search
- Auditing third-party documents
It can be especially useful when you are processing a large number of documents and need a consistent first-pass diagnostic.
Frequently Asked Questions
What is document extractability?
Document extractability describes how easily useful information can be obtained from a document in a machine-readable and structurally understandable form.
What does the AI Document Extractability Score measure?
It evaluates observable signals including text availability, document structure, machine readability, content cleanliness, paragraph and line characteristics, duplicate content, and character-level issues.
Is the score an AI accuracy score?
No. It is a diagnostic extractability score. It does not represent the accuracy of a particular AI model.
Does a score of 100 guarantee that AI can understand the document?
No. The score indicates that fewer detectable extractability problems were found. AI behavior depends on the model, parser, retrieval system, context, document type, and other factors.
Why does document structure matter?
Structure helps document-processing systems identify relationships between headings, paragraphs, lists, tables, and other content elements. Modern document parsing systems explicitly use these structural signals for search and RAG workflows.
Can a PDF be visually readable but poorly extractable?
Yes. A scanned or image-based PDF can look perfectly readable to a human while containing little or no machine-readable text.
Does OCR automatically make a document extractable?
Not necessarily. OCR creates machine-readable text, but recognition errors, missing content, reading-order problems, and poor structure can still reduce extractability.
Is document extractability the same as AI citation readiness?
No. Extractability is one factor that can affect how easily information can be parsed or reused. It does not guarantee retrieval or citation by an AI system.
Can I use this for RAG documents?
Yes. Extractability assessment can be used as an early document-quality check before chunking, indexing, and retrieval.
What should I do if my score is low?
Review the findings first. Depending on the problem, you may need OCR, text cleanup, better headings, improved paragraph structure, duplicate removal, or additional document preparation.
Related AI Document Tools
For a complete AI document preparation workflow, explore:
- AI OCR Quality Checker
- AI-Ready PDF Checker
- AI-Ready DOCX Checker
- Document Structure Analyzer for AI
- RAG Document Readiness Checker
- RAG Chunking Analyzer
- Document Chunking Calculator
- AI Document Safety Scanner
- AI Prompt Injection Document Scanner
- AI Document Link Safety Checker
- AI Document Metadata Privacy Checker
- PDF Text Extractor
- PDF & Document Tools