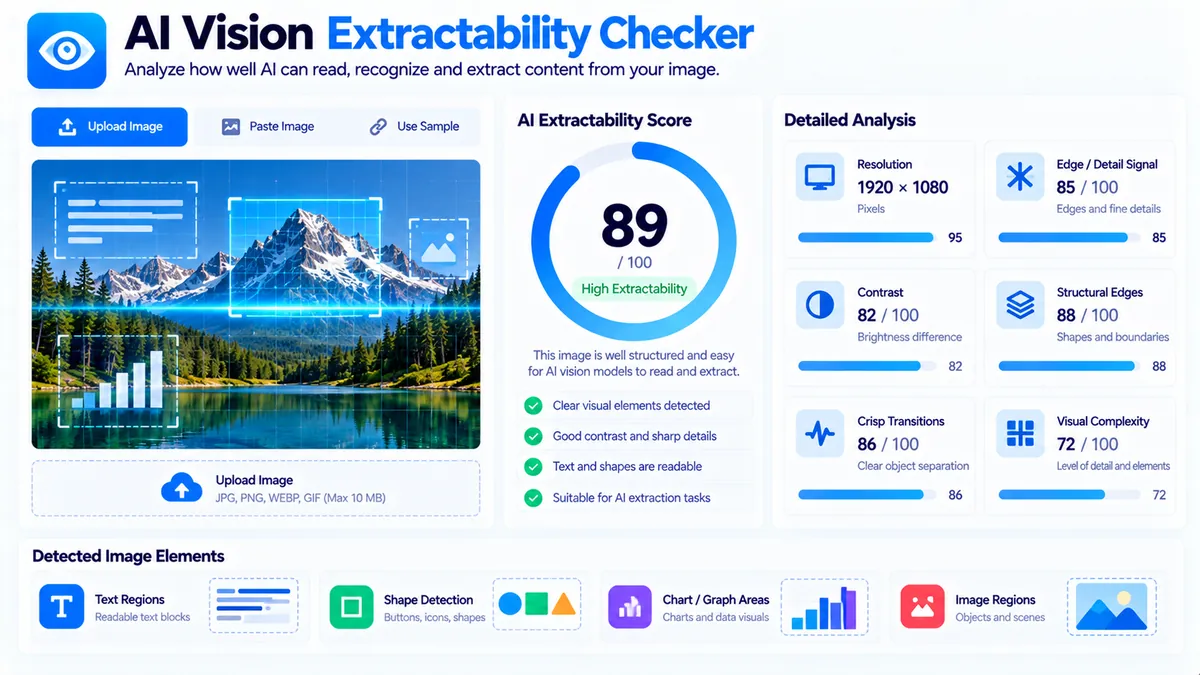
The AI Vision Extractability Checker estimates how easily visible information may be extracted from an image by a general AI vision workflow. It analyzes the image locally in your browser and evaluates measurable signals such as resolution, fine-detail structure, contrast separation, structural edges, crisp boundaries, visual complexity, and supported raster format. The result is a 0–100 extractability score with individual checks explaining which image characteristics may help or limit visual extraction.
AI Vision Extractability Checker
Estimate how easily an AI vision workflow may extract visible text, structure, fine detail and major visual regions from an image.
Upload an image to check extractability
AI vision extraction assessment
—
Extraction checks
How to Use the AI Vision Extractability Checker in Simple Steps
- Upload or drag and drop a JPG, PNG, WebP, GIF, BMP, or AVIF image into the checker. The browser-processing limit is 20 MB.
- Click Analyze Extractability to decode and analyze the image locally in your browser.
- Review the extractability score, image dimensions, format, file size, megapixels, aspect ratio, edge/detail signal, visual variance, and individual extraction checks.
- Use Copy Report, Copy JSON, Download JSON, or Download PDF to save the assessment. Use Load Example to test the tool or Clear to remove the current image and result.
Technical Breakdown: How the Extractability Assessment Works
The AI Vision Extractability Checker is a browser-side heuristic preflight tool. It does not send the selected image to an AI model, vision API, OCR service, or external processing endpoint.
The checker first decodes the image and scales the analysis canvas to a maximum dimension of 1,600 pixels. It then samples luminance and neighboring pixel differences to estimate several visual characteristics.
Resolution for Visible Detail
The tool checks the smallest image dimension because very small source images can limit the amount of recoverable visual detail. A larger image does not automatically guarantee good extraction, but sufficient pixel area gives small text, boundaries, and visual regions more room to remain distinguishable.
Fine-Detail and Edge Signal
The analyzer measures average luminance differences between neighboring sampled pixels. Higher edge activity can indicate more visible boundaries and fine structure, while very low edge activity can indicate an image with limited measurable detail.
Contrast Separation
The checker calculates luminance variation across the sampled image. Stronger separation between darker and lighter areas can make visible boundaries easier to distinguish. Low contrast can make text, objects, and regions less visually distinct.
Structural Edge Density
The tool counts stronger luminance transitions to estimate the amount of repeated structure and visual boundaries in the image. This can be useful for images containing layouts, diagrams, interface screenshots, charts, or other structured visual content.
Crisp Transition Signal
The checker also measures stronger local transitions as a practical signal for relatively crisp boundaries. A low signal can indicate that blur, softness, or weak transitions may make smaller visual elements harder to isolate.
Visual Simplicity and Clutter
Very high edge activity can also indicate a visually busy image. More detail is not always better: crowded regions can make individual elements harder to isolate. The tool therefore includes a separate visual-simplicity check rather than treating maximum edge activity as universally positive.
Supported Raster Format
JPG, PNG, WebP, and AVIF receive the full format score because they are common raster formats for modern browser and AI-image workflows. GIF and BMP remain supported when the browser can decode them, but receive a slightly lower format component in the heuristic.
The final score combines these individual measurements into a 0–100 heuristic. It is an image-level preflight signal, not a prediction of the output of a particular AI vision model.
A high score means the image has favorable measurable visual signals. It does not mean that an AI system will correctly extract every word, object, chart, table, diagram, or other element.
For broader image preparation before AI workflows, use the AI Image Readiness Checker. For OCR-focused preparation, use the Image OCR Readiness Analyzer when available. For image metadata inspection, use the AI Image Metadata Inspector.
Developer Snippets (Automate This Tool Offline)
The following examples provide practical offline measurements that can help you build your own image preflight workflow. They do not reproduce the PKCapra browser heuristic byte-for-byte and do not test a particular AI model.
Python with Pillow
Install Pillow with python -m pip install Pillow.
from pathlib import Path
from PIL import Image, ImageStat, ImageFilter

MAX_BYTES = 20 * 1024 * 1024

def analyze_image(path):
    file_path = Path(path)

    if not file_path.is_file():
        raise FileNotFoundError(file_path)

    size_bytes = file_path.stat().st_size

    if size_bytes > MAX_BYTES:
        raise ValueError("Image exceeds the 20 MB processing limit.")

    with Image.open(file_path) as image:
        width, height = image.size

        if not width or not height:
            raise ValueError("Image has no usable dimensions.")

        grayscale = image.convert("L")
        stats = ImageStat.Stat(grayscale)

        mean_luminance = stats.mean[0]
        luminance_stddev = stats.stddev[0]

        edges = grayscale.filter(ImageFilter.FIND_EDGES)
        edge_stats = ImageStat.Stat(edges)
        edge_signal = edge_stats.mean[0]

        megapixels = (width * height) / 1_000_000
        aspect_ratio = width / height

        return {
            "file": file_path.name,
            "format": image.format,
            "width": width,
            "height": height,
            "megapixels": round(megapixels, 2),
            "aspect_ratio": round(aspect_ratio, 4),
            "file_size_bytes": size_bytes,
            "mean_luminance": round(mean_luminance, 2),
            "visual_variance": round(luminance_stddev, 2),
            "edge_signal": round(edge_signal, 2)
        }

if __name__ == "__main__":
    import json
    import sys

    if len(sys.argv) != 2:
        raise SystemExit("Usage: python vision_extractability.py image.jpg")

    result = analyze_image(sys.argv[1])
    print(json.dumps(result, indent=2))
PowerShell
This PowerShell example performs a local image inventory using Windows PowerShell and .NET image handling.
param(
    [Parameter(Mandatory = $true)]
    [string]$Path
)

if (-not (Test-Path -LiteralPath $Path -PathType Leaf)) {
    throw "Image file was not found."
}

$file = Get-Item -LiteralPath $Path

if ($file.Length -gt 20MB) {
    throw "Image exceeds the 20 MB processing limit."
}

Add-Type -AssemblyName System.Drawing

$image = $null

try {
    $image = [System.Drawing.Image]::FromFile($file.FullName)

    if ($image.Width -le 0 -or $image.Height -le 0) {
        throw "Image has no usable dimensions."
    }

    $megapixels = ($image.Width * $image.Height) / 1000000
    $aspectRatio = $image.Width / $image.Height

    [pscustomobject]@{
        FileName = $file.Name
        Width = $image.Width
        Height = $image.Height
        Megapixels = [math]::Round($megapixels, 2)
        AspectRatio = [math]::Round($aspectRatio, 4)
        FileSizeBytes = $file.Length
    } | ConvertTo-Json -Depth 3
}
finally {
    if ($null -ne $image) {
        $image.Dispose()
    }
}
Node.js with Sharp
Install Sharp with npm install sharp.
const fs = require("fs/promises");
const path = require("path");
const sharp = require("sharp");

const MAX_BYTES = 20 * 1024 * 1024;

async function analyzeImage(filePath) {
  const absolutePath = path.resolve(filePath);
  const stat = await fs.stat(absolutePath);

  if (!stat.isFile()) {
    throw new Error("Image file was not found.");
  }

  if (stat.size > MAX_BYTES) {
    throw new Error("Image exceeds the 20 MB processing limit.");
  }

  const metadata = await sharp(absolutePath).metadata();

  if (!metadata.width || !metadata.height) {
    throw new Error("Image has no usable dimensions.");
  }

  const megapixels = (metadata.width * metadata.height) / 1000000;
  const aspectRatio = metadata.width / metadata.height;

  return {
    file: path.basename(absolutePath),
    format: metadata.format || null,
    width: metadata.width,
    height: metadata.height,
    megapixels: Number(megapixels.toFixed(2)),
    aspectRatio: Number(aspectRatio.toFixed(4)),
    fileSizeBytes: stat.size,
    hasAlpha: metadata.hasAlpha === true
  };
}

analyzeImage(process.argv[2])
  .then(result => {
    console.log(JSON.stringify(result, null, 2));
  })
  .catch(error => {
    console.error(error.message);
    process.exitCode = 1;
  });
Native Software Workaround: Image Extractability Inventory with Excel Power Query
Excel Power Query cannot calculate the same pixel-level extractability signals as the browser tool, but it can create a useful local inventory of images before an AI workflow.
- Put the images into a single folder.
- Open Excel and select Data → Get Data → From File → From Folder.
- Select the image folder and choose Transform Data.
- Keep the Name, Extension, Date modified, and Content columns.
- Add custom columns to classify images by extension, workflow, or review status.
- Filter for large files, unusual formats, or images that require manual inspection.
- Load the inventory into Excel and use it as a preflight queue before sending images to an AI vision workflow.
Power Query is useful for file-level organization, but it does not replace the browser-side visual measurements used by this checker. For edge signal, luminance variance, structural transitions, and crisp-boundary analysis, use the AI Vision Extractability Checker.
Frequently Asked Questions
What is an AI Vision Extractability Checker?
An AI Vision Extractability Checker is a browser-side image preflight tool that estimates whether visible visual information has measurable structure and separation that may support downstream AI vision extraction.
Does the checker send my image to an AI model?
No. The checker performs its analysis locally in the browser and does not send the image to an external AI model or vision API.
What does the extractability score measure?
The score combines measurable signals for resolution, fine-detail and edge activity, contrast separation, structural edge density, crisp transitions, supported format, and visual simplicity.
Is the score an AI accuracy prediction?
No. The score is a heuristic image-level measurement and does not predict the accuracy of a specific AI vision model, OCR engine, or vision API.
Which image formats are supported?
The checker accepts JPG, PNG, WebP, GIF, BMP, and AVIF images when the browser can decode them.
What is the maximum file size?
The browser-processing limit is 20 MB per image.
Why can a detailed image receive a lower score?
Very high visual activity is not always beneficial. Crowded or highly complex images can make individual elements harder to isolate, so the checker treats visual complexity separately from useful structural detail.
Why does contrast matter for AI vision extraction?
Contrast creates luminance separation between visual regions. Weak separation can make text, boundaries, objects, and other elements harder to distinguish.
Does the checker perform OCR?
No. The checker measures image characteristics related to visual extractability; it does not run an OCR engine or report the text contained in the image.
Can a high score guarantee that an AI can read my chart or diagram?
No. Chart and diagram interpretation depends on the actual content, layout, labels, resolution, model, prompt, and other factors. The score only reports measurable image-level signals.
Can I save the analysis?
Yes. The result provides Copy Report, Copy JSON, Download JSON, and Download PDF options.