
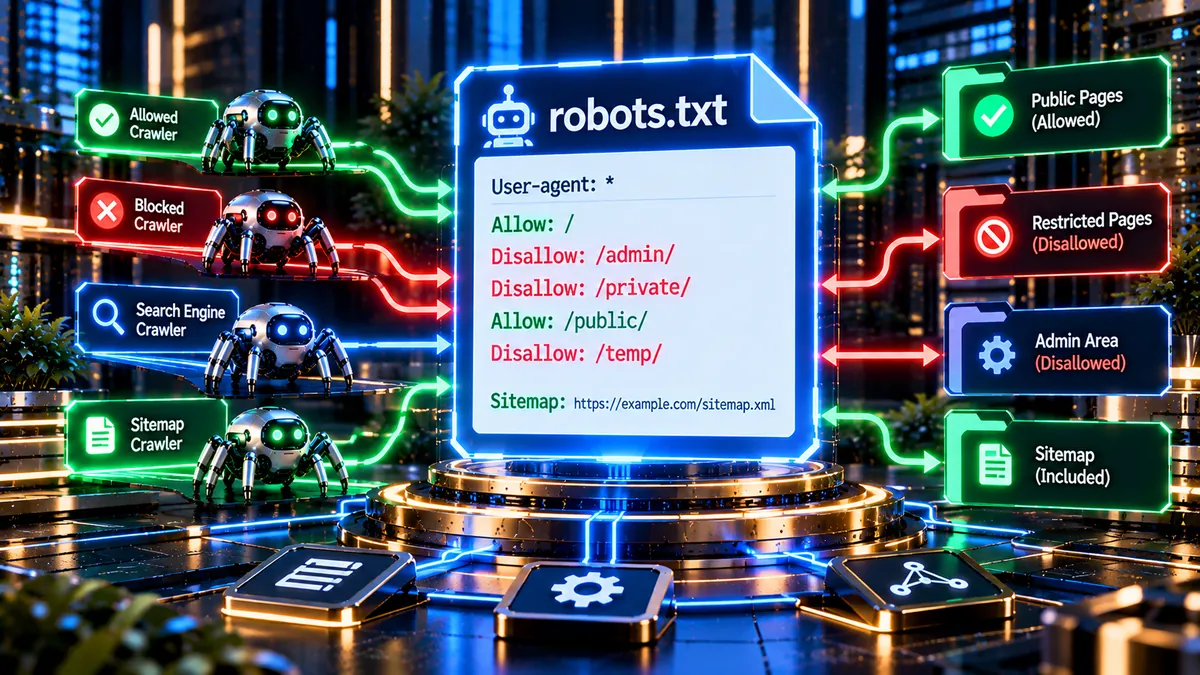
Create a custom robots.txt file for your website with PKCapra’s free Robots.txt Generator. Set the default crawler policy, control specific search and AI bots, add restricted paths, define crawl-delay directives, include your XML sitemap, and preview the complete robots.txt file in real time before downloading it.
Robots.txt Generator
Build a clean robots.txt file instantly with crawler access rules, bot controls, crawl-delay directives, restricted paths, and an XML sitemap reference.
Checked bot groups are explicitly blocked. Unchecked groups follow the default policy.
What Is a Robots.txt Generator?
A robots.txt file provides instructions that help automated crawlers understand which parts of a website they may access. PKCapra’s Robots.txt Generator makes it easier to create these directives without manually writing every rule.
The tool generates a clean robots.txt configuration based on the options you select. You can choose a default crawler policy, add specific bot rules, restrict directories, include a sitemap URL, and review the final output before downloading it.
For a broader technical SEO review, you can also use the Technical SEO Checker to examine other important website signals.
How the Robots.txt Generator Works
The generator uses your selected settings to build the robots.txt content directly in your browser. There is no API key, paid service, or external processing requirement.
Choose the rules you need, and the live preview updates automatically. This makes it easier to review the generated directives before using the file on your website.
The generated file can then be copied to your clipboard or downloaded as a plain-text file named robots.txt.
Set the Default Crawler Policy
The default crawler policy controls the general User-agent: * group.
You can choose between two main options:
- Allow all bots full access
- Disallow all bots from everything
The Allow option creates a broad access policy for crawlers unless additional restrictions are added.
The Refused option creates a broad blocking policy by using a site-wide Disallow: / directive.
Because a broad Disallow rule can prevent crawlers from accessing large parts of a website, review the generated output carefully before publishing it.
Add Crawl-Delay Directives
The generator provides optional crawl-delay settings for websites that need to include a delay directive.
Available options include:
- No Delay
- 5 Seconds
- 10 Seconds
- 20 Seconds
Crawl-delay support can vary between crawlers, so it should not be treated as a universal instruction for every search engine or bot.
Use the setting when it matches your crawler-management requirements rather than adding it automatically to every robots.txt file.
Add Your XML Sitemap
Enter your XML sitemap URL in the sitemap field to include a Sitemap directive in the generated file.
A typical sitemap entry looks like this:
Sitemap: https://example.com/sitemap.xml
If your website uses a sitemap index, you can enter its URL instead.
For example:
Sitemap: https://example.com/sitemap_index.xml
A sitemap helps crawlers discover URLs that you want them to know about. It does not override a robots.txt rule that prevents crawler access to a URL.
You can also review your sitemap structure with the XML Sitemap Analyzer.
Control Specific Search Engine Bots
The generator provides separate controls for several commonly encountered crawlers.
You can configure rules for:
- Googlebot
- Bingbot
- OAI-SearchBot
- ChatGPT-User
- ClaudeBot
- AhrefsBot
- SemrushBot
These options allow you to create more specific crawler groups instead of relying only on the general User-agent: * policy.
Specific crawler rules should be reviewed carefully because different user-agent groups can produce different crawling behavior.
Manage AI and Specialized Crawlers
Modern websites may receive requests from search crawlers, AI-related crawlers, SEO analysis bots, and other automated agents.
The Robots.txt Generator makes it easier to create explicit rules for selected AI and specialized crawlers.
You can use the available bot controls to define whether particular crawler groups should receive access or be restricted according to your website’s requirements.
Robots.txt should be used as a crawler-access mechanism, not as a security system for protecting private information.
Add Custom Restricted Paths
Use the dynamic restricted-path grid to add directories or URL paths that you want to block.
Examples include:
/wp-admin//cgi-bin//checkout//cart//private//temporary/
You can add multiple paths without manually rewriting the entire robots.txt file.
This is useful when a website has areas that do not need to be crawled as part of normal search-engine discovery.
For a wider crawl analysis, combine robots.txt testing with the Crawlability Checker.
Preview Your Robots.txt File in Real Time
The live preview console shows the generated robots.txt content as you configure the tool.
Changes to crawler policies, bot settings, restricted paths, crawl delay, and sitemap information are reflected in the preview automatically.
The dark code console also uses visual highlighting to make important directives easier to identify.
Allow: and Sitemap: directives are highlighted in green, while Disallow: directives are highlighted in red.
This visual distinction makes it easier to spot broad blocking rules before you publish the file.
Copy or Download the Generated Robots.txt File
Once your configuration is complete, you can use the Copy Code to Clipboard button to copy the generated rules.
The Download robots.txt File button creates a plain-text file locally in your browser.
The downloaded filename is exactly:
robots.txt
This means you can upload the generated file to the root directory of your website without manually creating or renaming a text document.
Robots.txt Rules and Crawlability
Robots.txt controls crawler access, but it is only one part of technical SEO.
A URL can be blocked from crawling without necessarily disappearing from every search result. Search engines may discover blocked URLs through other signals, depending on the situation.
Robots.txt should therefore be planned alongside other indexation and crawl controls.
Use the Indexability Checker to examine indexation-related signals separately.
Robots.txt Is Not a Security Mechanism
A robots.txt file does not provide authentication or access control.
The instructions are publicly accessible and are intended for compliant crawlers. A malicious or non-compliant bot can ignore them.
Do not place passwords, private information, confidential URLs, or security-sensitive data inside robots.txt.
Use proper authentication, authorization, server-level controls, or application security mechanisms when actual access protection is required.
Avoid Blocking Important Website Resources
A common robots.txt mistake is creating a rule that unintentionally blocks useful website content or important resources.
Before adding a broad path such as /, review the scope carefully.
Directory-based restrictions should also be checked for unintended URL matches.
For a complete website-level review, run the Full SEO Site Audit alongside your robots.txt checks.
Robots.txt for WordPress Websites
WordPress websites often contain administrative, system, and utility paths that may not need regular crawler access.
The generator can help create rules for selected paths such as /wp-admin/ or other areas that you specifically want to restrict.
However, WordPress sites can also rely on other SEO and indexing controls. A robots.txt configuration should therefore be reviewed together with your site’s actual indexation and crawl requirements.
Avoid copying a generic robots.txt configuration to every WordPress website without checking the site’s structure first.
When Should You Use a Robots.txt Generator?
A generator is useful when you need to create or revise a robots.txt file without manually formatting every directive.
Common use cases include:
- Creating a new robots.txt file
- Adding an XML sitemap
- Restricting selected directories
- Managing specific crawler groups
- Reviewing crawler access policies
- Preparing technical SEO changes
- Rebuilding a robots.txt file during a migration
- Checking a proposed crawler policy before deployment
The real-time preview is especially useful when several directives need to be combined into one file.
Common Robots.txt Mistakes
Blocking the Entire Website Accidentally
A rule such as Disallow: / can block crawler access across the website for the affected user-agent group.
Always inspect the generated output before publishing it.
Forgetting the Sitemap
A website can have a valid sitemap without listing it in robots.txt, but including the sitemap URL can make discovery of the sitemap location clearer to compatible crawlers.
Using Robots.txt for Security
Robots.txt should never be considered an access-control system.
Private resources should be protected with appropriate technical security controls.
Adding Too Many Broad Rules
Multiple broad rules can make a robots.txt file difficult to understand and maintain.
Use specific paths when a restriction only applies to a particular section.
Assuming Every Bot Supports Every Directive
Crawler support for directives such as crawl-delay can differ.
Do not assume that every crawler interprets every robots.txt instruction identically.
Frequently Asked Questions
What is a robots.txt file?
A robots.txt file is a text file placed at the root of a website that provides crawler access instructions using directives such as User-agent, Allow, and Disallow.
Can this tool create a robots.txt file automatically?
Yes. PKCapra’s Robots.txt Generator builds the file from your selected settings and lets you download the result as robots.txt.
Can I add a sitemap to robots.txt?
Yes. Enter your XML sitemap URL in the Sitemap field, and the generator adds a Sitemap: directive to the generated output.
Can I block specific bots?
Yes. The generator includes controls for Googlebot, Bingbot, OAI-SearchBot, ChatGPT-User, ClaudeBot, AhrefsBot, and SemrushBot.
Can I block specific directories?
Yes. The custom restricted-path grid allows you to add multiple paths that should receive Disallow directives.
Does robots.txt prevent pages from being indexed?
Not necessarily. Robots.txt primarily controls crawler access. Indexation involves additional signals and controls.
Is robots.txt a security feature?
No. Robots.txt is not an authentication or authorization mechanism. Non-compliant crawlers can ignore it.
Does the generator require an API key?
No. The generator runs directly in the browser and does not require an API key or paid external service.
Can I edit the generated robots.txt before downloading it?
The generator creates the output from the options you configure. Review the live preview carefully before copying or downloading the file.
Create a Robots.txt File Before Deployment
A carefully planned robots.txt file can make crawler-access rules easier to manage and understand.
Use PKCapra’s Robots.txt Generator to configure the default crawler policy, add specific bot controls, restrict selected paths, include your sitemap, and inspect the complete output before downloading it.
After creating the file, test the resulting rules with the Robots.txt Tester before deploying them to your live website.