
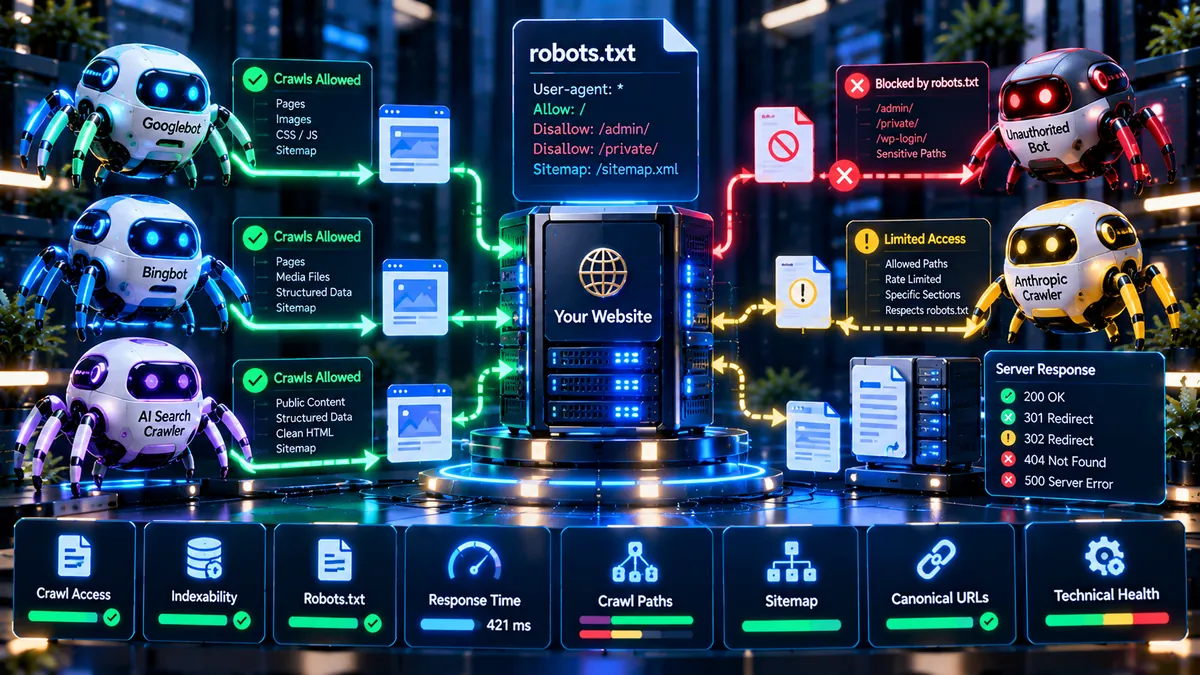
Check whether search engine and AI crawlers can access your website with PKCapra’s free Crawlability Checker. Simulate major crawler User-Agents, inspect robots.txt rules, detect robots and X-Robots-Tag restrictions, and measure server response time without requiring a paid SEO API.
Crawlability Checker
Test whether major search and AI crawler identities can access your website, inspect robots.txt rules, robots directives, response timing and bot-specific HTTP behavior.
Bot simulations reproduce User-Agent headers from the WordPress server. They show how the target responds to these requests at scan time and do not prove that every crawler will behave identically. robots.txt interpretation follows common crawler rules and should be reviewed with the site's full URL structure.
Only submit public URLs that you are authorized to analyze. Private, localhost, internal and reserved network targets are blocked by the network environment.
What Is a Crawlability Checker?
A crawlability checker is a website diagnostic tool that examines whether search engine and other web crawlers can access a URL and retrieve its content.
Crawlability is an important part of technical SEO because search engines need to access website resources before they can process pages and discover their content.
PKCapra’s Crawlability Checker provides a focused way to test crawler access, robots.txt rules, robots directives, response status, and server response time from one dashboard.
What Does the Crawlability Checker Check?
The Crawlability Checker combines several crawl-access signals into one diagnostic report.
It checks crawler-specific HTTP responses, robots.txt rules, X-Robots-Tag headers, meta robots directives, crawl restrictions, server response time, and timeout-related signals.
The tool also compares how the target URL responds when different crawler User-Agents are used.
Multi-Bot Header Simulation
Different crawlers can identify themselves through their User-Agent headers. A website may respond differently depending on the crawler requesting the page.
PKCapra’s Crawlability Checker simulates several important crawler identities so you can compare the server response.
The crawler simulations include Googlebot Desktop, Googlebot Mobile, Bingbot, OAI-SearchBot, ChatGPT-User, and ClaudeBot / Anthropic.
Googlebot Desktop
The checker simulates a Googlebot desktop crawler request and records the HTTP response, response time, and available crawl-related signals.
Googlebot Mobile
The checker also simulates a Googlebot mobile crawler so you can identify differences between desktop and mobile crawler responses.
Bingbot
Bingbot simulation helps identify whether the server responds differently when a Bing crawler User-Agent is used.
OAI-SearchBot and ChatGPT-User
The tool can simulate OAI-SearchBot and ChatGPT-User User-Agents to help inspect whether these crawler identities receive a different server response.
ClaudeBot / Anthropic
ClaudeBot simulation provides an additional view of how the target server responds to an Anthropic crawler identity.
Crawler HTTP Status Analysis
Each crawler simulation records the HTTP response returned by the target server.
A successful 200 response generally indicates that the requested resource was returned successfully to that simulated crawler.
Responses such as 401 Unauthorized, 403 Forbidden, and 503 Service Unavailable can indicate that the server, firewall, security layer, or another infrastructure component is treating the request differently.
A non-200 response should always be investigated in context because the cause may be related to authentication, rate limiting, security rules, temporary availability, or crawler-specific configuration.
For dedicated HTTP response testing, use the HTTP Status Checker.
Live robots.txt Parser
The robots.txt file can provide crawler access instructions at the website level.
The Crawlability Checker automatically attempts to retrieve the target website’s robots.txt file and analyzes available Disallow directives.
The parser checks rules that may affect Googlebot, Bingbot, OAI-SearchBot, ClaudeBot, or the wildcard User-Agent represented by an asterisk.
A robots.txt rule does not automatically mean that a website has an SEO problem. Some sections may intentionally be restricted from crawling.
Understanding Disallow Directives
A Disallow directive tells a matching crawler not to crawl the specified path according to the applicable robots.txt rules.
For example, a rule such as Disallow: /private/ can restrict crawling of URLs under the /private/ path for the applicable User-Agent.
The important question is whether the blocked path contains content that search engines or other intended crawlers should be able to access.
For dedicated robots.txt analysis, use the Robots.txt Analyzer.
Googlebot and Wildcard Crawl Restrictions
The Crawlability Checker reviews robots.txt rules that target Googlebot directly as well as wildcard rules using User-agent: *.
Wildcard rules can apply broadly to crawlers that follow the relevant robots.txt interpretation.
A Googlebot-specific rule can also override or change the effective behavior for Googlebot depending on the robots.txt configuration.
AI Crawler Access Checks
Modern websites may also be accessed by AI-related crawlers and retrieval systems.
The Crawlability Checker checks robots.txt rules relevant to OAI-SearchBot and other supported crawler identities.
This can help website owners identify whether an explicit robots.txt restriction affects a crawler they intend to allow.
A crawler restriction should always be evaluated according to the website owner’s intended access policy.
X-Robots-Tag Audit
Robots directives can also be delivered through the HTTP response header called X-Robots-Tag.
The Crawlability Checker examines available response headers for crawl and indexing-related directives.
Signals such as noindex, none, and other crawler directives can affect how a page is processed.
X-Robots-Tag is different from robots.txt because it is delivered with the HTTP response for a resource.
Meta Robots Audit
The HTML document can also contain a robots meta tag that provides page-level instructions.
The Crawlability Checker scans the returned HTML for meta robots directives such as noindex, none, nofollow, and nocrawl where detectable.
These directives are not automatically errors. They may be intentional for private, duplicate, staging, utility, or other pages that should not be indexed or followed.
Noindex, None and Nocrawl Signals
A noindex directive tells compatible crawlers that the page should not be included in search indexes according to the directive.
The none directive can combine restrictions equivalent to noindex and nofollow.
Nocrawl can appear in some crawler-control implementations, although support and interpretation can vary between systems.
Always review these signals in relation to the purpose of the page before treating them as a problem.
Server Response Time and Timeout Risk
Crawler access depends not only on whether a server returns content, but also on how reliably and quickly the server responds.
The Crawlability Checker measures the response time for crawler simulation requests and reports the available timing information.
Slow or inconsistent responses may indicate that the server needs further performance investigation.
A single response-time measurement is not enough to diagnose overall hosting or Core Web Vitals performance because server load, network conditions, caching, geography, and other factors can change response times.
Understanding Crawlability Status Colors
PKCapra uses a clear red, yellow, and green status system throughout the Crawlability Checker.
Green — Fully Crawlable or Accessible
Green indicates that the tested signal did not identify a blocking condition for the analyzed crawler or URL.
Yellow — Warning or Partial Restriction
Yellow indicates a warning, partial restriction, or condition that may require further investigation.
Red — Blocked or Critical
Red indicates a potentially blocking or critical crawlability condition such as an access-denied response or an explicit restriction affecting the tested resource.
How to Use the Crawlability Checker
Step 1: Enter the Website URL
Enter the public URL you want to analyze into the Crawlability Checker.
Step 2: Start the Crawlability Test
Run the checker to begin the crawler simulations and technical crawlability analysis.
Step 3: Review Each Bot
Review the HTTP status, response time, and crawlability state reported for each supported crawler User-Agent.
Step 4: Review robots.txt and Robots Directives
Check the robots.txt analysis together with X-Robots-Tag and meta robots results.
Step 5: Investigate Warnings
Review red and yellow findings carefully and determine whether each restriction is intentional or requires a configuration change.
Step 6: Download the Report
Use the PDF report option to save the crawlability dashboard and its findings for documentation or technical review.
Crawlability Checker vs. Technical SEO Checker
The Technical SEO Checker and Crawlability Checker focus on related but different technical questions.
The Technical SEO Checker examines a broader set of technical SEO signals including HTTP status, redirects, performance signals, indexability, canonicals, security headers, mixed content, and structured data.
The Crawlability Checker focuses specifically on crawler access, bot-specific HTTP responses, robots.txt restrictions, robots directives, and crawler response timing.
Crawlability Checker vs. Full SEO Site Audit
The Full SEO Site Audit provides a broader website-level crawl and technical SEO analysis.
The Crawlability Checker is designed as a focused diagnostic for understanding how different crawler identities interact with a specific URL and its crawl-control signals.
Using both tools can provide complementary information when investigating technical SEO and crawler-access issues.
Common Crawlability Problems
Googlebot Receives a 403 Response
A 403 response means the server refused the request. Investigate firewall rules, security plugins, CDN settings, bot protection, authentication requirements, and other access controls.
A Crawler Receives a 503 Response
A 503 response indicates that the requested service is unavailable. Temporary server overload, maintenance, rate limiting, or infrastructure problems can produce this response.
robots.txt Blocks an Important Section
If robots.txt disallows an important section of a website, review whether that restriction is intentional and whether it affects URLs that search engines need to crawl.
A Page Contains an Unexpected Noindex Directive
An unexpected noindex directive can prevent a page from being included in search results. Check the page template, SEO plugin settings, HTTP headers, and deployment configuration.
Different Bots Receive Different Responses
Different responses can occur because of firewall rules, bot-management systems, CDN configuration, server rules, or deliberate crawler policies.
Why Crawler User-Agent Testing Matters
A website may appear accessible in a normal browser while responding differently to automated crawlers.
User-Agent simulation provides another diagnostic perspective by showing how the server responds when different crawler identities are presented.
This does not prove how every real crawler will behave in every situation, because production crawler systems can use additional signals and infrastructure.
Robots.txt Is Only One Crawlability Signal
A website can have a valid robots.txt file and still have crawlability problems.
Servers, firewalls, CDNs, authentication systems, redirects, HTTP status codes, response time, meta robots directives, and X-Robots-Tag headers can all affect how a URL is accessed or processed.
That is why the Crawlability Checker combines multiple signals instead of relying only on robots.txt.
Related PKCapra SEO Tools
For broader technical SEO diagnostics, use the Technical SEO Checker.
For website-wide crawling and technical analysis, use the Full SEO Site Audit.
For robots.txt rules, use the Robots.txt Analyzer.
For HTTP response testing, use the HTTP Status Checker.
For redirect analysis, use the Redirect Checker.
For indexability signals, use the Indexability / Crawlability Analyzer.
Explore more website diagnostics in the SEO & Website Tools category.
Crawlability Checklist
Check that important URLs return an appropriate HTTP response to intended crawlers.
Review Googlebot desktop and mobile responses and investigate unexpected differences.
Check Bingbot and supported AI crawler responses where relevant to your access policy.
Review robots.txt for Googlebot, wildcard, OAI-SearchBot, and other relevant crawler restrictions.
Check important pages for unexpected noindex, none, nofollow, or other robots directives.
Review X-Robots-Tag headers for unexpected crawl or indexing restrictions.
Monitor server response time and investigate persistent timeout or availability problems.
Privacy and Processing
The Crawlability Checker is designed to analyze publicly accessible website URLs.
The tool does not require a paid SEO API, paid proxy network, or external VPS to perform its core checks.
Crawler simulations are performed through the PKCapra WordPress environment using the available server-side HTTP capabilities.
Only analyze websites and URLs that you are authorized to inspect.
Frequently Asked Questions
Is the Crawlability Checker free?
Yes. PKCapra’s Crawlability Checker is provided as a free online crawlability diagnostic without requiring a paid SEO API.
Which crawlers can it simulate?
The tool supports Googlebot Desktop, Googlebot Mobile, Bingbot, OAI-SearchBot, ChatGPT-User, and ClaudeBot / Anthropic simulations.
Does it check robots.txt?
Yes. The tool retrieves and analyzes the target website’s robots.txt file for relevant crawler restrictions.
Does it check Googlebot restrictions?
Yes. It checks applicable Googlebot-specific and wildcard robots.txt rules and reports relevant restrictions.
Does it check AI crawler restrictions?
Yes. The tool checks supported AI crawler identities and relevant robots.txt restrictions including OAI-SearchBot.
Does it check meta robots?
Yes. It scans returned HTML for detectable robots meta directives such as noindex, none, nofollow, and nocrawl.
Does it check X-Robots-Tag?
Yes. The checker examines available HTTP response headers for X-Robots-Tag directives.
Does it measure server response time?
Yes. The tool records response timing for crawler simulation requests and reports available response-time signals.
Does a 403 always mean a website has an SEO problem?
No. A 403 means the server refused the request, but the reason may be intentional security policy, authentication, bot protection, firewall configuration, or another access-control mechanism.
Does a robots.txt Disallow always block indexing?
No. Robots.txt primarily controls crawling. It should not be treated as a universal indexing directive, and search systems can have different behaviors when URLs cannot be crawled.
Can I use the tool on another website?
Yes. The checker is designed for publicly accessible URLs. Only analyze websites and URLs that you are authorized to inspect.
Final Thoughts
Crawlability is one of the foundations of technical SEO because important content needs to remain accessible to the crawlers that a website intends to serve.
A website can look completely normal in a browser while a crawler encounters a different HTTP response, robots.txt restriction, robots directive, X-Robots-Tag header, or server timeout.
PKCapra’s Crawlability Checker brings these signals together so you can compare crawler access and identify potential restrictions from one dashboard.
For deeper technical analysis, continue with the Technical SEO Checker or the Full SEO Site Audit.