
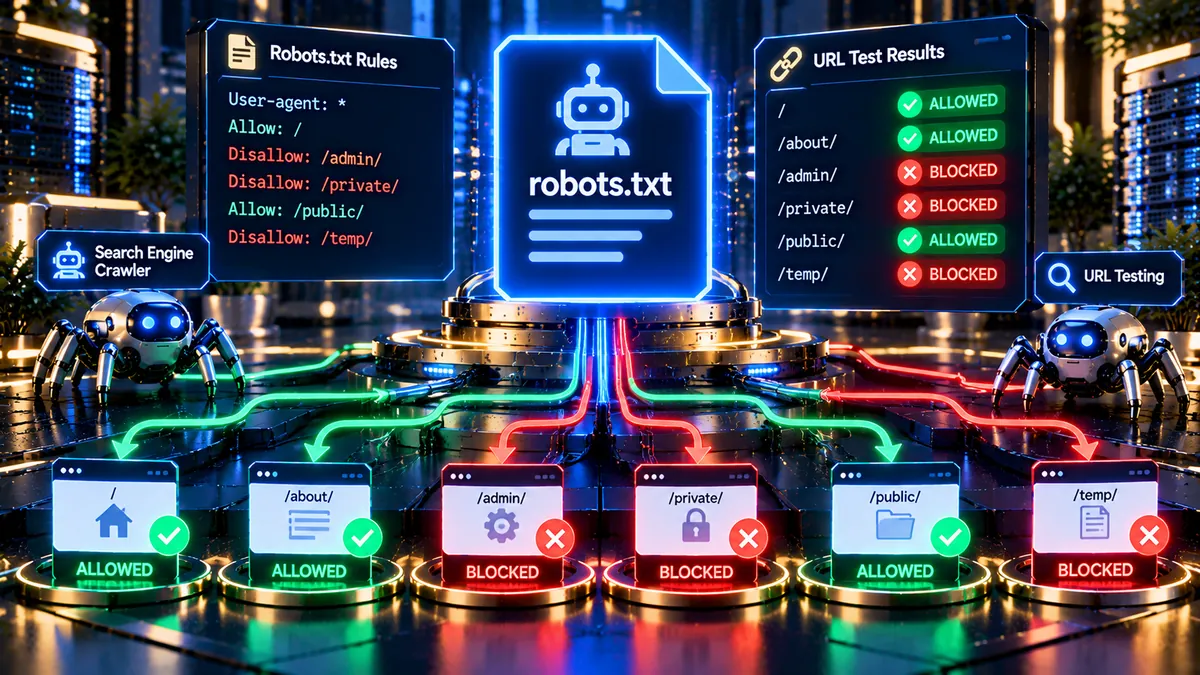
Robots.txt Tester helps you determine whether a specific URL path is allowed or blocked by a website’s live robots.txt rules. Enter a website domain and the path you want to test, and the tool fetches the site’s robots.txt file, identifies the applicable crawler rules, evaluates Allow and Disallow directives, and reports the resulting crawl status.
Unlike a simple robots.txt viewer, this tester evaluates the actual relationship between a target path and the rules defined in the live file. It can help SEO professionals, developers, site owners, and technical auditors identify crawler restrictions before they affect site discovery and crawling.
Robots.txt Tester
Test a URL path against a website's live robots.txt rules for Googlebot, Bingbot, or the default crawler group.
What Is a Robots.txt Tester?
A robots.txt tester analyzes the robots.txt file published at a website’s root and checks whether a particular URL path matches an Allow or Disallow rule.
The robots.txt file is part of the Robots Exclusion Protocol. It contains crawler instructions organized into user-agent groups and rules. The current standardized protocol is documented in RFC 9309. :contentReference[oaicite:1]{index=1}
For example, a website may contain:
User-agent: *
Disallow: /private/
If you test:
/private/account/
the applicable rule can block that path for crawlers using the generic user-agent group.
Our Robots.txt Tester makes this evaluation easier by showing the matching directive and the final crawl verdict in a clear dashboard.
How the Robots.txt Tester Works
The tool follows a simple testing workflow:
- Enter the target website domain.
- Enter the URL path or slug you want to test.
- The tool retrieves the live robots.txt file.
- The robots.txt content is separated into crawler groups and directives.
- Applicable User-agent groups are identified.
- Allow and Disallow rules are matched against the requested path.
- The most specific matching rule is evaluated.
- The final result is displayed as ALLOWED or BLOCKED.
- The complete fetched robots.txt file remains available for inspection.
This makes it useful for testing individual URLs without manually reading an entire robots.txt file.
Test Allow and Disallow Rules
The most important directives for crawl testing are Allow and Disallow.
A Disallow rule can restrict crawler access to a path:
User-agent: *
Disallow: /admin/
An Allow rule can provide access to a more specific path:
User-agent: *
Disallow: /admin/
Allow: /admin/public/
When rules overlap, specificity matters. The standardized robots.txt protocol uses the most specific matching rule based on the length of the matching path. Google also documents longest-match processing and uses the least restrictive rule when conflicting matching rules have equivalent specificity. :contentReference[oaicite:2]{index=2}
This is important because simply finding the word “Disallow” in robots.txt does not automatically mean that every URL beneath that path is blocked.
Test Specific URL Paths
You can test a complete path such as:
/wp-admin/
/shop/
/products/example-product/
/private/account/
/category/news/
The tester evaluates the path against the applicable robots.txt rules instead of treating the entire file as a simple blocklist.
For technical SEO audits, this can help identify unexpected crawler restrictions on important sections of a website.
User-Agent Rules Matter
Robots.txt rules are organized into User-agent groups. A crawler looks for the group that applies to its product token. If no specific matching group exists, the generic * group can apply. RFC 9309 specifies case-insensitive matching for crawler product tokens and describes how matching groups are handled. :contentReference[oaicite:3]{index=3}
This means a robots.txt file can treat different crawlers differently.
For example:
User-agent: Googlebot
Disallow: /private/
User-agent: *
Disallow: /temporary/
A Googlebot request and a generic crawler request may therefore encounter different applicable rules.
The Robots.txt Tester identifies the relevant user-agent group used during the evaluation and displays it in the results dashboard.
Wildcards in Robots.txt Rules
Modern robots.txt processing supports special pattern characters.
The * character can represent zero or more characters, while $ can indicate the end of a URL pattern. Google documents these wildcard behaviors in its robots.txt specification guidance. :contentReference[oaicite:4]{index=4}
For example:
Disallow: /*.pdf$
can target URLs ending in .pdf.
Similarly:
Disallow: /private/*
can match paths beginning with /private/.
A reliable tester therefore needs to evaluate patterns rather than simply compare strings. This tool uses pattern-based rule evaluation to process these common robots.txt matching patterns.
Understanding the Test Result
The dashboard provides three important pieces of information.
Crawl Status Verdict
The main result shows whether the tested path is:
ALLOWED
or
BLOCKED
An ALLOWED result means the applicable robots.txt rules do not prevent crawling of the tested path.
A BLOCKED result means a matching Disallow rule applies to the tested path.
Matching Directive
The tester displays the specific directive that determined the result.
For example:
Disallow: /wp-admin/
This makes the result easier to audit because you can immediately identify the rule responsible for the decision.
User-Agent Targeted
The dashboard also identifies the applicable crawler group, such as:
Googlebot
or:
This is important when a website contains different robots.txt rules for different crawlers.
Why Robots.txt Testing Matters for Technical SEO
Robots.txt is primarily a crawler-access control mechanism. It can influence which URL paths compliant crawlers are requested to access, making it an important part of technical SEO.
An accidental rule such as:
User-agent: *
Disallow: /
can prevent compliant crawlers from accessing the site’s entire URL space.
A more targeted restriction may also unintentionally block an important section:
User-agent: *
Disallow: /products/
If product pages are important to organic search visibility, this type of restriction deserves investigation.
Using a robots.txt tester can make these problems easier to identify during technical SEO audits.
For broader technical analysis, you can also use the Technical SEO Checker and Crawlability Checker on PKCapra.
Robots.txt Does Not Replace Indexing Controls
A robots.txt rule and an indexing directive serve different purposes.
Robots.txt primarily communicates crawler access instructions. It is not an authentication mechanism and should not be treated as a security barrier. RFC 9309 explicitly notes that robots.txt rules are not access authorization. :contentReference[oaicite:5]{index=5}
If a resource must be protected from unauthorized access, use proper authentication and server-side access controls.
For SEO purposes, robots.txt should also be considered alongside other technical signals. A crawl restriction is not the same thing as a noindex directive.
You can investigate related indexing controls with the Indexability Checker and Noindex Checker.
Robots.txt Tester for WordPress Websites
WordPress websites frequently contain crawler-sensitive paths such as:
/wp-admin/
/wp-includes/
/wp-content/
/feed/
/author/
/search/
Some websites also use custom rules for ecommerce, membership, staging, filtering, tracking, or internal search URLs.
Testing individual paths can help determine whether a robots.txt configuration is behaving as intended.
For example, an ecommerce website may want search engines to crawl product pages while restricting internal search parameters. A robots.txt tester can help validate individual paths before changes are deployed.
Inspect the Raw Robots.txt File
The tester displays the complete fetched robots.txt content beneath the results.
This provides useful context when a result needs further investigation.
You can inspect:
- User-agent groups
- Allow directives
- Disallow directives
- Sitemap declarations
- Wildcard patterns
- Comments
- Multiple crawler groups
- Other robots.txt records
Seeing the raw file together with the evaluated result makes troubleshooting faster.
Robots.txt Testing for SEO Audits
A robots.txt test can be useful during:
- Technical SEO audits
- Website migrations
- WordPress redesigns
- Ecommerce launches
- Robots.txt changes
- New website deployments
- International SEO projects
- Crawl-budget investigations
- Large-site audits
- Search visibility troubleshooting
For a broader audit, combine robots.txt testing with the Full SEO Site Audit and Indexability Checker.
Common Robots.txt Problems
Blocking an Important Directory
A broad Disallow rule can unintentionally restrict valuable pages.
Example:
Disallow: /blog/
If the blog contains important organic landing pages, this rule should be reviewed carefully.
Blocking Too Broadly
A rule such as:
Disallow: /
has a very broad effect for crawlers that use the applicable group.
This can create serious crawl-access problems if it is published accidentally.
Allow and Disallow Rules Overlap
Consider:
Disallow: /shop/
Allow: /shop/products/
The more specific matching rule can affect the result for URLs inside /shop/products/. Rule specificity is therefore important when interpreting overlapping directives. :contentReference[oaicite:6]{index=6}
Testing the Wrong User-Agent
A robots.txt file can contain separate rules for different crawlers.
Testing only the generic * group may therefore produce a different interpretation from a crawler-specific group.
Assuming Robots.txt Is a Security Feature
Robots.txt communicates crawler preferences and rules. It does not prevent users or malicious software from directly requesting a URL. :contentReference[oaicite:7]{index=7}
Frequently Asked Questions
What does a robots.txt tester do?
A robots.txt tester checks a specific URL path against the rules published in a website’s live robots.txt file and reports whether the path is allowed or blocked according to the applicable rules.
Where is robots.txt located?
A standard robots.txt file is published at the root of a host, normally at:
/robots.txt
For example, a website using example.com would normally publish its file at https://example.com/robots.txt.
Does Disallow always block a URL?
Not necessarily. The applicable rule depends on the matching user-agent group and the specific Allow and Disallow rules. More specific matching rules can take precedence over broader rules. :contentReference[oaicite:8]{index=8}
What is the difference between Allow and Disallow?
Disallow tells compliant crawlers not to access matching paths, while Allow permits matching paths within the applicable rule set. When rules overlap, specificity affects which rule applies.
What does User-agent: * mean?
The asterisk represents the generic crawler group. If a crawler does not have a more specific matching group, the generic group can provide the applicable rules. :contentReference[oaicite:9]{index=9}
What does the * wildcard mean in a robots.txt path?
The * wildcard can represent zero or more characters in a robots.txt path pattern. Google documents support for this wildcard in its robots.txt interpretation. :contentReference[oaicite:10]{index=10}
What does $ mean in robots.txt?
The $ character indicates the end of a URL pattern. It can be used when a rule should match a URL ending at a specific pattern. :contentReference[oaicite:11]{index=11}
Can robots.txt protect private information?
No. Robots.txt is not an access-control or authentication system. Sensitive information should be protected using appropriate server-side security controls. :contentReference[oaicite:12]{index=12}
Is this Robots.txt Tester free?
Yes. The PKCapra Robots.txt Tester is designed for free use without premium SEO APIs, paid proxies, or VPS infrastructure.
Can I inspect the complete robots.txt file after testing?
Yes. The tool displays the fetched robots.txt content in a dedicated raw-text inspection area so you can review the complete rule set alongside the test result.
Test Robots.txt Rules Before They Affect Your Crawlability
A small robots.txt change can affect crawler access across an entire website. Testing individual paths provides a practical way to understand how Allow and Disallow directives interact before making SEO or development changes.
Use the PKCapra Robots.txt Tester to fetch the live robots.txt file, test a specific path, identify the applicable directive, and understand the resulting crawl status from one dashboard.