
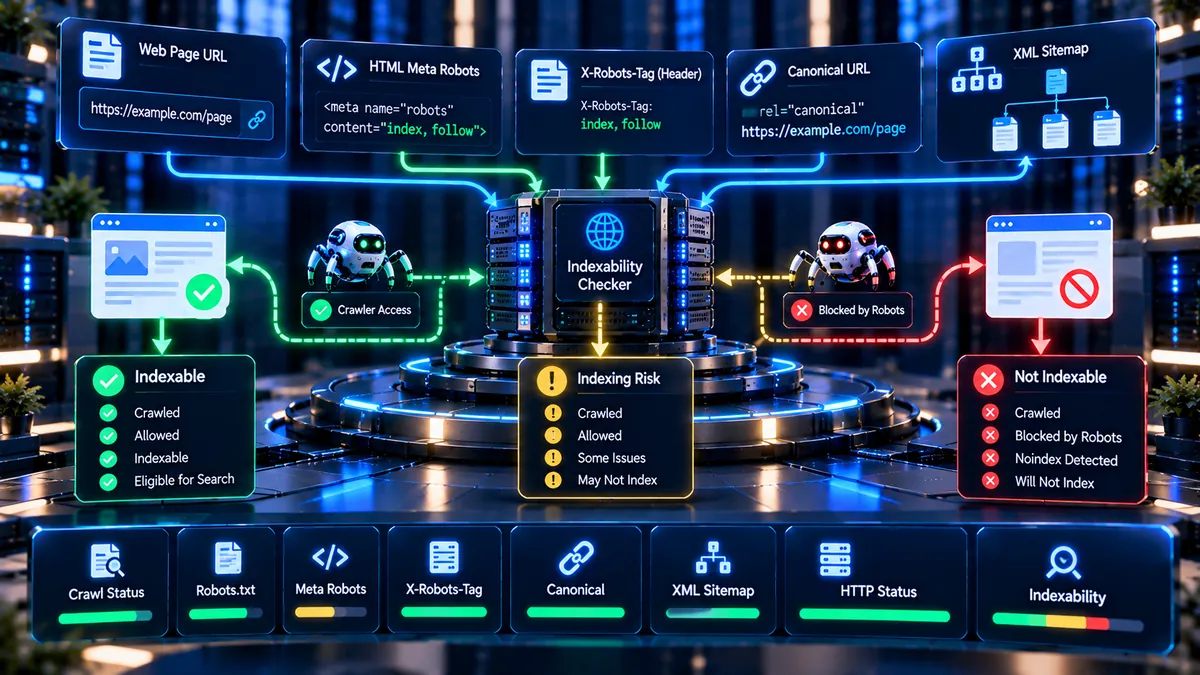
Check whether a webpage can be indexed by search engines with PKCapra’s free Indexability Checker. Analyze meta robots directives, X-Robots-Tag headers, canonical URLs, HTTP status, and XML sitemap signals to find indexing barriers quickly.
Indexability Checker
Determine whether a URL can be indexed by combining HTTP status, robots directives, X-Robots-Tag, canonical alignment and XML sitemap signals.
Indexability is determined from signals visible to the local WordPress fetch at scan time. A sitemap entry can support discovery but is not itself a requirement for indexing, and canonical signals are hints rather than absolute indexing guarantees.
Only submit public URLs that you are authorized to analyze. The checker uses your WordPress server's native HTTP transport and does not send the URL to a paid SEO API.
What Is an Indexability Checker?
An Indexability Checker examines the signals that affect whether search engines can index a webpage. It looks beyond simple HTTP access and checks the instructions that control search visibility.
A page can load normally in a browser and still remain outside a search index. Meta robots directives, HTTP headers, canonical URLs, and other signals can change how search engines treat that page.
PKCapra’s Indexability Checker brings these signals together in one clear report. The tool highlights blocking issues, potential risks, and positive indexing signals.
How Does the Indexability Checker Work?
Enter a public webpage URL and start the analysis. PKCapra fetches the page and examines its HTTP response, HTML head, response headers, canonical configuration, and discovered XML sitemap information.
The checker then combines the available signals into an indexability assessment. A blocking directive receives a red status, a potential indexing risk receives a yellow status, and a healthy signal receives a green status.
Meta Robots Sniffer
The tool scans the HTML head for robots directives that can restrict indexing. It checks both standard robots instructions and Google-specific directives.
Robots Meta Tag
A page can use a meta name="robots" tag to control crawler behavior. The checker looks for directives such as noindex, none, and noarchive.
The report also checks meta name="googlebot". Google-specific instructions can affect how Google handles the page even when broader robots settings look different.
Noindex Detection
The noindex directive tells search engines not to include the page in their search index. PKCapra marks this signal clearly so you can identify a direct indexing restriction.
A noindex directive may be intentional on private, staging, utility, duplicate, or temporary pages. Review the page purpose before changing the directive.
None and Noarchive Signals
The none directive can combine multiple crawler restrictions. The checker reports this signal as part of the overall indexability assessment.
The noarchive directive controls cached-page storage. It does not mean the same thing as noindex, so the report keeps these signals separate.
X-Robots-Tag Header Inspector
Web servers can send indexing instructions through the X-Robots-Tag HTTP response header. These instructions can apply before a crawler processes the page HTML.
PKCapra checks the response headers for directives such as noindex. It also recognizes Googlebot-specific X-Robots-Tag instructions.
A header-level noindex signal can therefore become a major indexing barrier. The checker separates this signal from HTML-based robots directives so you can identify the source of the restriction.
Canonical Tag Alignment
Canonical URLs help search engines understand which URL represents the preferred version of similar pages. The Indexability Checker reads the page’s canonical tag and compares it with the submitted URL.
Self-Referential Canonical
A self-referential canonical points back to the page being analyzed. This setup usually provides a clear canonical signal for that URL.
PKCapra reports the canonical relationship so you can confirm whether the requested URL and canonical URL align.
Non-Canonical Page
A different canonical URL can indicate that another page represents the preferred version. PKCapra flags this situation as a potential non-canonical page.
Search engines make the final indexing decision. A canonical tag acts as a signal rather than an absolute command, so the report presents it as an important indexing factor.
For a dedicated canonical analysis, use the Canonical URL Checker.
XML Sitemap Presence Check
XML sitemaps help search engines discover important URLs. The Indexability Checker looks for available sitemap information and checks whether the analyzed URL appears in discovered sitemap data.
A URL that appears in a sitemap has a useful discovery signal. However, sitemap presence does not guarantee indexing.
Similarly, a URL missing from a sitemap does not automatically mean that search engines cannot index it. Other discovery paths may exist through internal links or external references.
Use the XML Sitemap Analyzer when you need a deeper sitemap-focused analysis.
HTTP Status and Indexability
HTTP status plays an important role in indexability. Search engines need to access a usable response before they can evaluate many page-level signals.
A successful 200 OK response provides a normal starting point for indexing analysis. Redirects, client errors, server errors, and unavailable responses require further review.
Use the HTTP Status Checker for a focused HTTP response check.
Indexability Status Explained
Green — Indexable
A green result means the checked signals do not show a clear indexing blocker. The page can therefore proceed to normal search-engine evaluation.
Green does not guarantee that Google or another search engine will index the page. Search engines use many additional quality, relevance, duplication, and ranking signals.
Yellow — Indexing Risk
A yellow result identifies a signal that deserves attention. A non-self-referencing canonical, missing sitemap presence, or another configuration issue can require review without proving that indexing is blocked.
Check the surrounding signals before making a technical change. Some yellow conditions can be intentional.
Red — Not Indexable or Blocked
A red result identifies a direct or serious indexing barrier. Noindex directives and certain HTTP response conditions can prevent a page from entering a search index.
Review the source of the restriction first. Remove a blocking directive only when the page should genuinely appear in search results.
Indexability Checker vs Crawlability Checker
Crawlability and indexability describe different parts of the search process. Crawlability focuses on whether crawlers can access and process a resource.
Indexability focuses on whether search engines receive signals that allow the page to enter their index. A page can therefore be crawlable while still carrying a noindex instruction.
Use the Crawlability Checker to investigate crawler access, robots.txt rules, User-Agent responses, and response-time risks.
Indexability Checker vs Technical SEO Checker
The Technical SEO Checker reviews a broader set of technical SEO signals. It covers HTTP behavior, redirects, performance signals, security headers, canonical settings, and structured data.
The Indexability Checker narrows that analysis around search-index eligibility. It combines the most relevant indexing signals into a focused verdict.
Indexability Checker vs Full SEO Site Audit
A full site audit examines many pages and technical SEO factors across a website. It can reveal wider structural problems that a single-page indexability test cannot show.
Use the Full SEO Site Audit when you need a broader website-level assessment.
Common Indexing Problems
Several technical configurations can stop a page from entering search results. Common examples include:
- Noindex meta robots directives.
- Googlebot-specific noindex instructions.
- X-Robots-Tag noindex headers.
- Non-canonical URL configuration.
- Unexpected HTTP status responses.
- Incorrect redirects.
- Pages that should appear in search but lack useful discovery signals.
The correct fix depends on why the page should exist and how the website intends to use it.
How to Use the Indexability Checker
1. Enter a Public URL
Enter the complete public webpage URL that you want to inspect.
2. Start the Check
Run the Indexability Checker and allow the tool to fetch the requested page.
3. Review the Signals
Review robots directives, X-Robots-Tag headers, canonical alignment, HTTP status, and sitemap presence.
4. Check the Final Verdict
Use the red, yellow, and green status indicators to identify blockers and potential indexing risks.
5. Download the Report
Use the PDF report option when you need to save or share the completed indexability analysis.
Why Indexability Matters for SEO
Search visibility starts with a page being eligible for indexing. Strong content cannot perform in organic search if technical instructions prevent search engines from storing the page.
Indexability checks can also help during website migrations, redesigns, technical SEO audits, staging launches, and large content updates.
Regular checks can catch accidental noindex directives or canonical changes before they create wider SEO problems.
Indexability and Technical SEO Workflows
Indexability works best as part of a wider technical SEO workflow. Start with the page status, inspect crawler access, review indexing directives, and then investigate canonical and sitemap signals.
For broader technical checks, explore the SEO & Website Tools collection on PKCapra.
Related PKCapra SEO Tools
Use these tools alongside the Indexability Checker for a deeper technical SEO workflow:
Indexability Checklist
Before publishing an important page, confirm that the page returns an appropriate HTTP response. Check the robots directives and X-Robots-Tag header next.
Review the canonical URL after that. Make sure it represents the intended preferred URL.
Finally, review sitemap presence and your wider internal linking structure. These checks help search engines discover and evaluate important pages.
Privacy and Processing
PKCapra’s Indexability Checker does not require a premium SEO API, paid proxy, or external SEO subscription. The analysis runs through the PKCapra WordPress tool engine using server-side web requests and local parsing.
Only submit public URLs that you are authorized to analyze. Results are generated for the submitted analysis and should be reviewed before making production SEO changes.
Frequently Asked Questions
What does an Indexability Checker do?
An Indexability Checker reviews technical signals that can allow or prevent a webpage from entering a search index. PKCapra checks robots directives, X-Robots-Tag headers, canonical URLs, HTTP status, and sitemap presence.
Does a 200 status guarantee indexing?
No. A 200 response means the server returned a successful response, but it does not guarantee search-engine indexing. Search engines consider many additional signals.
Does noindex prevent indexing?
A noindex directive tells search engines not to include the page in their index. The directive can appear in HTML robots metadata or through an X-Robots-Tag HTTP header.
Why does the checker flag a different canonical URL?
A different canonical URL tells search engines that another URL represents the preferred version. PKCapra flags this relationship because the submitted URL may not be the canonical page.
Does sitemap presence guarantee indexing?
No. A sitemap helps search engines discover URLs, but it does not guarantee that they will index every submitted URL.
Can a page be crawlable but not indexable?
Yes. A crawler may access a page successfully while a noindex directive prevents search indexing. That distinction makes crawlability and indexability separate technical SEO checks.
Is the Indexability Checker free?
Yes. PKCapra provides the Indexability Checker as a free online SEO tool without requiring a premium SEO API subscription.
Final Thoughts
Indexability problems can remain hidden when a page appears normal in a browser. A focused technical check can reveal the directives and signals that search engines receive.
Use PKCapra’s Indexability Checker to review these signals from one dashboard. When a problem appears, inspect the underlying directive before changing the website configuration.