
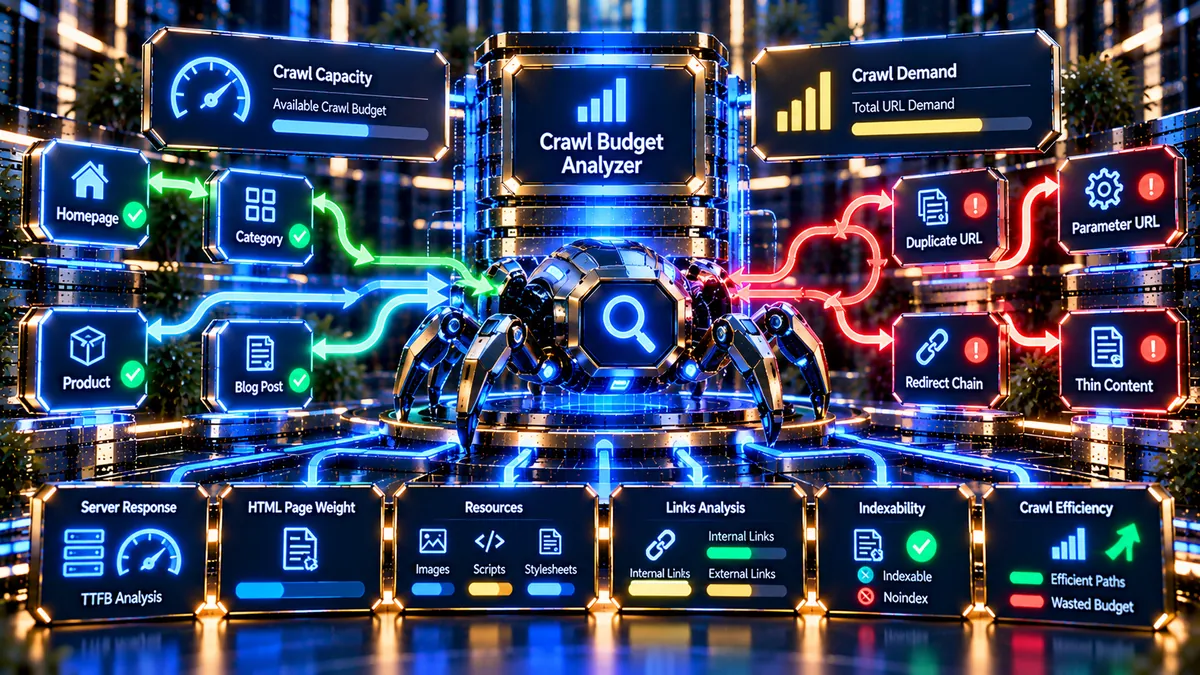
Crawl Budget Analyzer helps you identify page-level signals that can affect crawling efficiency, including server response time, HTML payload size, resource counts, and indexation-related signals.
Enter a public page URL to analyze the page’s HTTP response, Time to First Byte (TTFB), payload size, links, images, scripts, stylesheets, inline resources, and noindex signals. The report then classifies the fetched response and highlights potential crawl-efficiency concerns.
Crawl Budget Diagnostic
Resource & Indexation Signals
Report Actions
What Is Crawl Budget?
Crawl budget is the amount of crawling resources that Google can and wants to use for a particular site. Google describes crawl budget in terms of two main components: the site’s crawl capacity limit and crawl demand.
The crawl capacity limit is influenced by how much load Google’s crawling can place on a server. When a site responds consistently and quickly, Google can potentially crawl more efficiently. Slow responses, server errors, and rate-limiting signals can cause crawling activity to decrease.
Crawl demand is influenced by factors such as the size of a site’s known URL inventory, how frequently content changes, and the perceived importance or popularity of URLs.
This distinction matters because crawl budget is not simply a fixed number of pages that Google promises to crawl every day.
For small websites and sites whose pages are crawled promptly, crawl-budget optimization may not require extensive work. Google specifically positions its detailed crawl-budget guidance primarily for very large or frequently updated websites.
What Does This Crawl Budget Analyzer Check?
PKCapra’s Crawl Budget Analyzer performs a focused page-level diagnostic rather than attempting to calculate Google’s actual crawl budget for an entire domain.
The tool fetches the URL and analyzes the returned response.
It checks:
- HTTP response status
- Time to First Byte (TTFB)
- HTML payload size
- Final URL after redirects
- Internal links
- External links
- Images
- Script elements
- Stylesheets
- Inline scripts
- Inline styles
- X-Robots-Tag noindex
- Meta robots noindex
- Indexation-waste signals
- Overall page classification
The result gives you a practical snapshot of whether the individual page has signals that deserve further technical investigation.
HTTP Status Matters
The HTTP status code is one of the first things to inspect when diagnosing crawling problems.
A successful 200 response means the server successfully returned content, but it does not guarantee that Google will index the page.
Redirect responses such as 301 and 302 require additional interpretation because the crawler has to process the redirect and its destination.
Server errors such as 5xx can be particularly important because Google states that server errors can cause crawling to slow down.
The analyzer therefore reports the HTTP status alongside the rest of the page diagnostics so you can investigate the response before drawing conclusions about crawl efficiency.
If a page returns an unexpected status code, use the HTTP Status Checker for a focused status-code investigation.
TTFB: Why Server Response Time Matters
TTFB, or Time to First Byte, measures how long it takes before the first byte of the HTTP response becomes available after the request is made.
A consistently slow server response can reduce how efficiently crawlers can retrieve pages. Google’s crawl-budget documentation specifically notes that stable response times and TTFB are part of crawl-health considerations.
A high TTFB does not automatically mean that a page has a crawl-budget problem. It is a diagnostic signal that should be interpreted alongside server capacity, availability, page type, crawl demand, and other technical conditions.
Use the result as a starting point for investigation rather than as an official Google crawl-budget score.
For a broader performance investigation, compare the result with PKCapra’s Page Speed Analyzer.
HTML Payload Size and Page Weight
The analyzer reports the size of the fetched HTML response.
Large HTML documents can contain substantial amounts of markup, inline CSS, inline JavaScript, structured data, navigation elements, or other content that increases the amount of data a crawler needs to retrieve and process.
Page weight should not be interpreted as a standalone ranking or crawl-budget score. The useful question is whether unnecessary page weight is contributing to slower responses, excessive resource usage, or inefficient crawling.
For example, a page containing hundreds of unnecessary inline styles may deserve a different investigation from a page whose size is primarily caused by meaningful content.
The analyzer therefore exposes both the payload size and resource counts so you can see where further investigation may be useful.
Resource Counts: What the Page Loads
The report separates several resource categories:
Internal Links
Internal links help reveal how much navigational structure exists within the fetched HTML.
A large number of internal links is not automatically a problem. Large sites can legitimately have substantial internal linking.
The important question is whether the links support useful site architecture or create unnecessary URL discovery paths.
External Links
External links show how many outbound links were found in the fetched HTML.
These are reported separately from internal links so the page’s linking structure is easier to interpret.
Images
The image count shows how many image elements were detected in the HTML.
Images can contribute to resource requests and page complexity, although the count alone does not tell you the transferred size or performance impact of every image.
Scripts
The script count shows the number of script elements detected.
Large numbers of scripts can increase page complexity, particularly when combined with substantial inline JavaScript or third-party dependencies.
Stylesheets
Stylesheet counts identify external CSS resources referenced by the page.
A high stylesheet count does not automatically indicate a crawl problem, but it can be useful when investigating pages with unnecessary resource overhead.
Inline Scripts
Inline script counts show how many script blocks are embedded directly in the HTML.
Inline code can be useful and intentional, but excessive inline JavaScript can increase HTML size and make page source heavier.
Inline Styles
Inline styles are also counted because they can significantly increase HTML payload size when used extensively.
If a page contains a very high number of inline style declarations, investigate whether CSS can be consolidated or moved into more maintainable external stylesheets.
Noindex Signals and Indexation Waste
The analyzer checks two important noindex-related signals:
X-Robots-Tag: noindex- Meta robots
noindex
These signals matter because a page that is deliberately excluded from indexing may not represent the same crawl objective as a page that should be discoverable and indexed.
However, there is an important distinction between crawling and indexing.
A noindex directive does not mean that Google will never request the URL. Google’s crawl-budget documentation specifically warns that using noindex to control crawl budget can still require Google to crawl the page before discovering the directive.
If a URL should not be crawled at all, the appropriate technical solution depends on the situation. For example, robots.txt can be appropriate for pages or resources that you do not want Google to crawl.
Do not blindly add noindex to URLs simply because they are not intended to rank. First determine whether the URL should be crawled, indexed, redirected, canonicalized, or removed.
For a dedicated robots investigation, use the Robots.txt Analyzer.
Understanding the Page Classification
The analyzer provides a page classification based on the signals it detects.
An indexable response generally means that the fetched response does not contain the specific noindex signals checked by the tool and that the response is suitable for further technical investigation.
This does not mean that Google will definitely index the page.
Indexing can depend on many other factors, including content quality, canonicalization, duplication, crawlability, search demand, technical accessibility, and Google’s own indexing systems.
If the page needs a deeper indexability investigation, use the Indexability & Crawlability Analyzer.
What a Healthy Crawl Signal Means
A healthy result should be interpreted as:
- The HTTP response is behaving normally for the tested request.
- The server response time is within the analyzer’s configured diagnostic range.
- The HTML payload is not unusually heavy according to the tool’s thresholds.
- Resource counts do not trigger the analyzer’s heavier-resource warnings.
- No checked noindex signals were detected.
- No immediate indexation-waste signal was identified.
It does not mean that the entire website has a healthy crawl budget.
Crawl efficiency is a site-level concern, and a single URL cannot represent every URL, template, parameter combination, response type, or crawler interaction on a large website.
Common Crawl Budget Problems
Duplicate URL Inventory
Large numbers of duplicate or near-duplicate URLs can increase the number of URLs search engines need to discover and evaluate.
Examples include:
- URL parameters
- Tracking parameters
- Multiple URL variations
- Duplicate category paths
- Filter combinations
- Sorting URLs
- Session-based URLs
Google recommends managing the URL inventory so crawling resources are focused on useful content.
For canonical relationships and duplicate URL behavior, use the URL Canonicalization Checker.
Long Redirect Chains
Redirects are sometimes necessary, but unnecessarily long redirect chains add extra requests and can make crawling less efficient.
Google’s crawl-budget guidance specifically recommends avoiding long redirect chains.
Use the Redirect Checker when a page has unexpected redirects or when you need to inspect the redirect path.
Server Errors
Repeated 5xx responses can indicate server availability or capacity problems.
Google states that server errors can cause crawlers to temporarily reduce crawling.
If this analyzer finds a server error, do not treat it simply as an SEO score problem. Investigate the underlying hosting, application, database, PHP, caching, CDN, or infrastructure issue.
Soft 404 Pages
A soft 404 occurs when a page appears to return usable content at the HTTP level but effectively represents a missing or unavailable page.
Google’s crawl-budget guidance specifically recommends eliminating soft 404 errors because these URLs can continue to be crawled.
A dedicated soft-404 diagnostic can be used when that analysis is available in your technical SEO workflow.
Unnecessary URL Parameters
Parameter-heavy websites can create large numbers of URL variations that contain substantially similar content.
Examples include:
?sort=price?filter=blue?session=123- tracking parameters
- internal search parameters
Not every parameter is harmful, and some parameters are required for legitimate functionality.
The goal is to identify URL patterns that create unnecessary crawlable variations.
Outdated Sitemaps
Your XML sitemap should represent the URLs you actually want search engines to discover and process.
Keep sitemap URLs current and use accurate lastmod information when applicable.
Use PKCapra’s XML Sitemap Analyzer to investigate sitemap structure and contents.
Crawl Budget vs. Crawlability vs. Indexability
These concepts are related but different.
Crawlability asks whether a crawler can access a URL.
Indexability asks whether the content is eligible to be considered for indexing.
Crawl budget concerns how much crawling a search engine can and wants to perform across a site’s known URLs.
For example:
A page can be crawlable but have a noindex directive.
A page can be indexable but difficult for crawlers to discover.
A page can return 200 but still not be indexed.
A site can have technically accessible pages but waste crawling resources through large numbers of duplicate URLs.
Understanding these distinctions prevents incorrect fixes.
A Practical Crawl Budget Audit Workflow
For a single suspicious page, use this sequence:
Step 1: Run the Crawl Budget Analyzer
Enter the exact URL and review:
- HTTP status
- TTFB
- payload
- resource counts
- noindex signals
- final URL
- page classification
Step 2: Check the HTTP Response
If the status is unexpected, investigate it with the HTTP Status Checker.
Step 3: Inspect Redirects
If the URL redirects, check the complete redirect behavior with the Redirect Checker.
Step 4: Check Indexability
If the page should appear in search, investigate its crawlability and indexability using the Indexability & Crawlability Analyzer.
Step 5: Check Canonicalization
If multiple URLs represent the same or substantially similar content, inspect canonical relationships with the URL Canonicalization Checker.
Step 6: Review Robots Rules
If crawling appears restricted, inspect the site’s robots.txt configuration using the Robots.txt Analyzer.
Step 7: Review Sitemap Coverage
Confirm that important URLs are represented correctly in your sitemap using the XML Sitemap Analyzer.
Step 8: Investigate Site-Level Crawl Data
For large sites, supplement page-level diagnostics with Google Search Console’s Crawl Stats report.
Google’s Crawl Stats report provides actual historical information such as crawl requests, download size, average response time, host status, response types, file types, crawl purpose, and Googlebot type.
That data is more appropriate for understanding actual Google crawling behavior across a site than a single-page diagnostic.
When Should You Worry About Crawl Budget?
Crawl budget deserves more attention when a website has:
- A very large number of URLs
- Frequently changing content
- Large numbers of duplicate URLs
- Parameter-driven URL variations
- Many redirects
- Significant numbers of server errors
- Slow server responses
- Soft 404s
- Large or outdated sitemap inventories
- A substantial number of URLs reported as discovered but not indexed
- Evidence of inefficient crawling in Search Console or server logs
For smaller websites, crawl budget is often not the first technical issue to investigate.
Google’s own documentation states that detailed crawl-budget optimization is primarily intended for very large and frequently updated websites.
How to Improve Crawl Efficiency
There is no single crawl-budget switch that makes Google crawl more pages.
Instead, improve the conditions that allow crawlers to use their resources efficiently.
Focus on:
- Removing unnecessary duplicate URLs
- Reducing unnecessary parameter variations
- Avoiding long redirect chains
- Fixing persistent server errors
- Eliminating soft 404s
- Keeping XML sitemaps current
- Improving server response consistency
- Reducing unnecessary page complexity
- Preventing important resources from being accidentally blocked
- Maintaining clear internal linking
- Using canonicalization correctly
- Removing obsolete URLs where appropriate
Do not block URLs merely because you want to “save” crawl budget. Google notes that robots.txt should be used for URLs or resources you do not want crawled at all, and that unused crawl capacity is not automatically redistributed to other URLs unless the site is already hitting its crawl capacity limit.
Crawl Budget Is Not an Official PKCapra Score
PKCapra’s analyzer reports diagnostic signals from the URL you submit.
It does not have access to Google’s internal crawl allocation systems and does not claim to reproduce Google’s actual crawl-budget calculation.
The tool should therefore be used as a technical diagnostic layer.
For actual Google crawl behavior, combine this report with:
- Google Search Console Crawl Stats
- Page Indexing data
- Server access logs
- XML sitemap data
- robots.txt configuration
- Redirect analysis
- Canonical analysis
- Indexability checks
This combination provides a much more complete picture than any single crawl-budget score.
Frequently Asked Questions
What is crawl budget?
Crawl budget is the amount of crawling resources that Google can and wants to use for a site. Google describes it using crawl capacity and crawl demand.
Does every website need crawl-budget optimization?
No. Google says its detailed crawl-budget guidance is primarily intended for very large or frequently updated websites. Smaller sites generally do not need to optimize crawl budget as a major standalone project.
Does a slow TTFB reduce crawl budget?
Slow response times can affect crawl capacity because Google considers server response behavior when adjusting crawling activity. A single slow request does not prove that a site has a crawl-budget problem.
Does a 200 status mean Google will index the page?
No. A 200 response means the server successfully returned content, but indexing is a separate process and is not guaranteed.
Does noindex save crawl budget?
Not necessarily. Google explains that Google may still request a URL to discover the noindex directive. If a URL should not be crawled at all, consider the appropriate crawl-control method instead.
Do redirects waste crawl budget?
Redirects require crawler requests, and Google recommends avoiding long redirect chains because they can have a negative effect on crawling efficiency.
Does robots.txt improve crawl budget?
Robots.txt can prevent Google from crawling URLs or resources that you do not want crawled. However, it should be used deliberately rather than as a generic way to redistribute crawl capacity.
Can this tool calculate my website’s actual Google crawl budget?
No. The tool performs a page-level technical diagnostic. It does not have access to Google’s internal crawl allocation systems or your site’s historical Googlebot crawl data.
Why does my page show an indexable response but still isn’t indexed?
Indexability is only one part of Google’s processing pipeline. A technically indexable response does not guarantee indexing. Other factors can include canonicalization, duplication, content quality, discovery, technical accessibility, and Google’s own systems.
What should I use with the Crawl Budget Analyzer?
For a deeper investigation, combine it with PKCapra’s HTTP Status Checker, Redirect Checker, Indexability & Crawlability Analyzer, URL Canonicalization Checker, Robots.txt Analyzer, and XML Sitemap Analyzer.
Final Takeaway
Crawl budget is primarily a large-site crawling efficiency problem, not a simple page-speed score.
The most useful approach is to identify URLs and technical conditions that make crawling less efficient: unnecessary URL variations, duplicate content, long redirect chains, server errors, soft 404s, slow responses, outdated sitemaps, and other avoidable crawl paths.
PKCapra’s Crawl Budget Analyzer gives you a focused starting point by examining the actual HTTP response, response timing, HTML payload, resource counts, and indexation-related signals for the URL you submit.
Use the result as a diagnostic signal, then combine it with Search Console Crawl Stats, server logs, sitemap data, robots.txt analysis, redirect checks, canonical checks, and indexability diagnostics when investigating larger or more complex websites.