
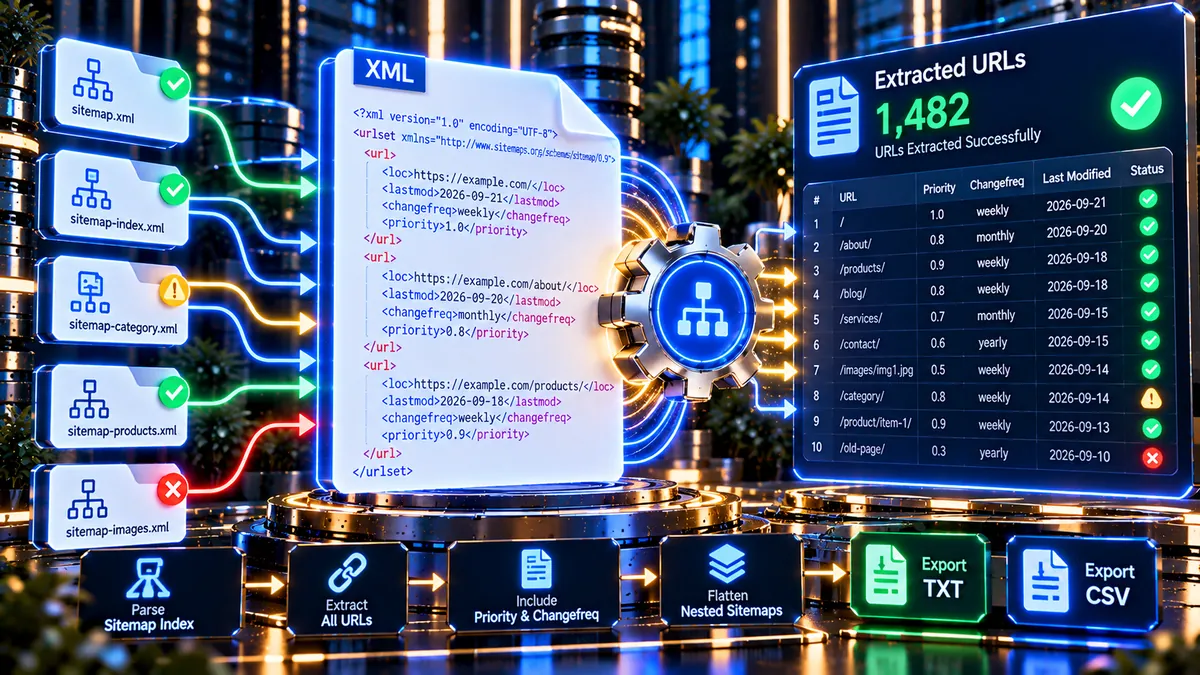
Extract URLs from XML sitemaps with PKCapra’s free XML Sitemap URL Extractor Pro. Process standard sitemaps and sitemap indexes, resolve nested sitemap files, extract URL data with optional priority and change frequency values, and export the results as TXT or CSV.
XML Sitemap URL Extractor Pro
Flatten sitemap indexes, extract URL nodes, collect priority and change-frequency metadata, and export the resulting URL list instantly.
Extracted URL Matrix
Clean URL strings with optional priority and change-frequency metadata.
| # | URL | Priority | Change Frequency |
|---|
What Is an XML Sitemap URL Extractor?
An XML Sitemap URL Extractor is a tool that reads an XML sitemap and converts its URL entries into a clean, usable list.
PKCapra’s XML Sitemap URL Extractor Pro can process standard XML sitemaps and sitemap index files. When an index contains multiple child sitemaps, the extractor can follow the nested sitemap structure and combine the discovered URLs into one consolidated result.
The extracted URL list can then be copied or downloaded as a TXT or CSV file for SEO audits, website migrations, URL analysis, content reviews, and spreadsheet-based workflows.
For deeper sitemap structure and metadata analysis, use the XML Sitemap Analyzer.
How the XML Sitemap URL Extractor Pro Works
Enter the URL of the XML sitemap you want to process.
The tool fetches the sitemap and determines whether it contains standard URL entries or references to additional sitemap files.
If the source is a sitemap index, the extractor resolves the available child sitemaps and processes their URL entries within its safe processing limits.
The extracted URLs are then organized into a searchable and paginated data table.
You can copy the complete URL list or export it directly as a TXT or CSV file.
Extract URLs from a Standard XML Sitemap
A standard XML sitemap contains URL entries inside a <urlset> structure.
Each URL normally contains a <loc> element that identifies the address of the resource.
The extractor reads these URL values and creates a clean list without requiring you to manually inspect the XML source.
This is useful when you need to quickly obtain every submitted URL from a sitemap.
Extract URLs from a Sitemap Index
Large websites often use sitemap index files instead of placing every URL into one XML document.
A sitemap index can reference multiple child sitemaps.
For example, a website may separate URLs into different files for:
- Posts
- Pages
- Products
- Categories
- Images
- Other content groups
The extractor detects the index structure and can resolve the nested sitemap references so the resulting output contains the URLs from the available child sitemap files.
Flatten Nested Sitemaps into One URL List
A sitemap index creates a hierarchy of XML documents.
Manually opening every child sitemap can become inefficient when a website has many sitemap files.
The nested sitemap flattening engine processes the available sitemap relationships and combines extracted URL entries into a single result.
This makes it easier to work with large sitemap architectures without manually collecting URLs from each XML file.
Extract the URL Location
The primary data extracted from each sitemap entry is the <loc> value.
The resulting list contains the URL addresses submitted through the sitemap.
This can be useful for:
- URL inventory creation
- SEO audits
- Migration planning
- Redirect mapping
- Content reviews
- Technical SEO analysis
- Spreadsheet analysis
- Broken URL investigations
A clean URL inventory can also be compared against crawl or indexation data to identify differences.
Extract Priority Values
Some XML sitemap implementations include a <priority> value for URL entries.
When available, PKCapra’s extractor captures the priority information alongside the URL.
This allows you to preserve additional sitemap metadata when exporting the extracted data.
Priority values should be interpreted in the context of the sitemap implementation rather than treated as a guarantee of search-engine ranking or indexing importance.
Extract Change Frequency Values
The extractor can also capture the <changefreq> value when it is present in the sitemap.
This provides additional context about how frequently a sitemap entry is intended to change.
The value is optional and may not be present in every sitemap.
When available, it is included in the extracted data so you can review the original sitemap information alongside the URL.
View Extracted URLs in a Data Grid
After processing completes, the extracted URLs are displayed in a structured data grid.
The table provides a practical way to scan the resulting URL inventory without opening the raw XML document.
The interface uses pagination to keep large URL collections manageable.
Each extracted URL can be reviewed through the table before you export the complete dataset.
Total URLs Extracted
The dashboard displays the total number of URL entries extracted during processing.
This gives you an immediate overview of the size of the sitemap URL inventory.
The count is especially useful when comparing sitemap coverage before and after a website migration, content update, or sitemap configuration change.
Sitemap Processing State
The dashboard identifies whether the source was processed as a standard XML sitemap or as a sitemap index that required nested processing.
A successful index process indicates that child sitemap references were resolved within the configured processing boundaries.
This makes the processing state easier to understand before reviewing the extracted URL data.
Total Nested Sitemaps Resolved
When the submitted resource is a sitemap index, the dashboard reports the number of nested sitemap documents resolved.
This helps you understand the scale of the sitemap structure behind the original URL.
A higher nested sitemap count can indicate a larger or more segmented sitemap architecture.
Export URLs as TXT
The Download TXT File action creates a plain-text URL list.
The resulting file contains one extracted URL per line.
TXT export is useful when you need a simple URL list for:
- Manual review
- Command-line workflows
- Redirect planning
- URL filtering
- Content inventories
- Other text-based SEO tools
The export is generated directly in the browser.
Export URLs as CSV
The Download CSV File action creates a spreadsheet-ready dataset.
CSV export is useful when you want to sort, filter, compare, or enrich the extracted URL inventory in spreadsheet software.
Depending on the available sitemap metadata, the exported data can preserve URL-related fields such as priority and change frequency.
This makes CSV particularly useful for technical SEO audits and migration projects.
Copy All Extracted URLs
The Copy All URLs button lets you copy the complete extracted URL list to your clipboard.
A temporary confirmation message indicates that the URL list has been copied successfully.
This is useful when you want to move the extracted URLs into another application without generating a separate file.
Memory-Safe Sitemap Processing
Large sitemap collections can contain thousands of URLs and multiple child sitemap documents.
The extractor uses controlled processing limits to reduce unnecessary memory and execution pressure on standard WordPress hosting environments.
This approach is designed to make the tool practical without requiring a premium crawling API, paid proxy network, or dedicated VPS.
Large websites should still consider their hosting resources when processing very large sitemap structures.
Detect Empty Sitemaps
An empty sitemap does not provide a usable URL inventory.
The extractor identifies situations where no usable URL entries are obtained and presents the result as an issue rather than returning a misleading successful extraction count.
If the sitemap is unexpectedly empty, investigate the sitemap generator, URL filters, caching layer, or source XML.
Handle Sitemap Fetch Problems
The extractor must first retrieve the sitemap before it can process the XML.
Connection failures, timeouts, inaccessible URLs, server errors, or unexpected responses can therefore prevent URL extraction.
When this occurs, the result is presented as a failed fetch state so you can investigate the source URL separately.
For HTTP-level testing of a specific resource, use the HTTP Status Checker.
Green, Yellow, and Red Extraction States
PKCapra uses visual status colors to make extraction results easier to interpret.
Green
Green states indicate successful URL extraction, successful sitemap processing, and successful nested sitemap resolution.
Yellow
Yellow states identify conditions that deserve attention, such as large XML resources or nested sitemap processing warnings.
These conditions do not necessarily mean that the extracted URLs are invalid.
Red
Red states indicate serious processing problems such as connection failures, empty sitemap results, or unsuccessful fetch operations.
This helps distinguish data-quality warnings from actual extraction failures.
XML Sitemap URL Extraction for SEO Audits
A sitemap URL list can provide a useful inventory of the URLs a website is submitting for crawler discovery.
You can use the extracted dataset to investigate:
- URL coverage
- Sitemap segmentation
- Redirect targets
- Content inventories
- Migration URL lists
- Potentially outdated URLs
- Sitemap changes
- URL duplication
- Crawl and indexation differences
For a wider technical SEO workflow, combine extraction with the Technical SEO Checker and Full SEO Site Audit.
XML Sitemap URL Extraction for Website Migrations
Website migrations often require a reliable inventory of existing URLs.
A sitemap can provide one useful source for building that inventory.
The extractor lets you turn sitemap data into a downloadable CSV or TXT file that can be reviewed during migration planning.
You can then compare the old URL list with the new URL structure and build additional redirect or mapping workflows.
Sitemap data should not be treated as the only source of URLs during a migration because pages may exist outside the sitemap.
Use Extracted URLs for Redirect Analysis
Extracted sitemap URLs can be useful when reviewing redirect behavior.
After exporting the URLs, you can identify addresses that need redirect verification or compare old and new URL structures.
For individual redirect investigations, use the Redirect Checker.
The extracted sitemap list can also provide a useful starting point for larger migration analysis.
Use Extracted URLs for Indexation Audits
A sitemap URL list can be compared with indexation data to identify URLs that are submitted but may not be indexed.
The extraction itself does not determine whether a URL is indexed.
It simply provides the sitemap URL inventory.
Use the Indexability Checker to investigate the indexability signals of individual URLs.
XML Sitemap URL Extractor for WordPress
WordPress websites may generate sitemap indexes automatically or through SEO plugins.
Large WordPress websites can therefore have multiple child sitemap files containing different types of content.
The XML Sitemap URL Extractor Pro can help turn this sitemap structure into a consolidated URL inventory.
This can be useful when auditing a WordPress website without manually opening every sitemap file.
Common XML Sitemap Extraction Problems
Sitemap URL Cannot Be Fetched
If the sitemap cannot be retrieved, extraction cannot begin.
Verify the sitemap URL and investigate the server response, firewall configuration, CDN behavior, or hosting restrictions.
Sitemap Contains No URLs
An empty result may indicate an empty sitemap, incorrect XML structure, filtering rules, or a sitemap generator problem.
Sitemap Index Contains Missing Child Files
A sitemap index may reference child sitemap URLs that no longer exist or cannot be accessed.
Review the referenced sitemap locations and their server responses.
Duplicate URLs Across Child Sitemaps
Large sitemap systems can sometimes contain the same URL in multiple sitemap files.
A consolidated extraction makes it easier to identify repeated URL entries during subsequent analysis.
Very Large Sitemap Resources
Large XML documents can consume more server resources during processing.
The extractor therefore uses controlled processing limits to reduce unnecessary memory and execution pressure.
XML Sitemap URL Extractor vs XML Sitemap Analyzer
The two tools serve different primary purposes.
The XML Sitemap Analyzer is designed to analyze sitemap structure, URL data, images, last modified information, and sample HTTP statuses.
The XML Sitemap URL Extractor Pro is focused on turning sitemap data into a practical URL inventory that can be copied or exported.
Use the Analyzer when you need detailed sitemap analysis.
Use the URL Extractor when your main goal is to obtain the sitemap’s URL list in a reusable format.
XML Sitemap URL Extractor vs XML Sitemap Validator
The XML Sitemap Validator focuses on XML syntax and structural validation.
The URL Extractor focuses on extracting usable URL data.
A practical workflow can therefore be:
- Validate the XML structure.
- Analyze the sitemap architecture.
- Extract the URL inventory.
- Review individual URLs for technical SEO issues.
Each tool addresses a different stage of sitemap investigation.
Frequently Asked Questions
What is an XML Sitemap URL Extractor?
It is a tool that reads an XML sitemap and extracts its URL entries into a clean, reusable list.
Can it extract URLs from a sitemap index?
Yes. The extractor can resolve nested child sitemap files and combine their extracted URLs.
Can it process multiple child sitemaps?
Yes. Sitemap index processing can follow available child sitemap references within the tool’s configured safety limits.
Can it extract priority?
Yes. When <priority> is present, the extractor can capture the value alongside the URL.
Can it extract change frequency?
Yes. When <changefreq> is available, the extractor can preserve that sitemap metadata.
Can I download the extracted URLs?
Yes. You can download the URL list as either TXT or CSV.
Can I copy all URLs at once?
Yes. The Copy All URLs button copies the complete extracted URL list to the clipboard.
Does it require an API key?
No. The tool is designed to run through the WordPress environment without requiring a paid API or external scraping service.
Can it handle large sitemap structures?
The extractor uses controlled processing limits to reduce memory and execution pressure. Very large sitemap architectures may still require processing in manageable batches.
Does extracting a URL mean that the URL is indexed?
No. Extraction only confirms that the URL was found in the sitemap data. It does not confirm crawlability, indexability, or search-engine indexing.
Can I use the extracted URLs for a migration?
Yes. TXT and CSV exports can provide a useful URL inventory for migration planning and further analysis.
Extract Your Sitemap URLs into a Clean Dataset
XML sitemaps can contain valuable URL inventory data, but manually collecting those URLs becomes inefficient as sitemap structures grow.
PKCapra’s XML Sitemap URL Extractor Pro converts standard XML sitemaps and nested sitemap indexes into a practical URL dataset. You can review the extracted URLs, copy the complete list, or download the results as TXT and CSV files.
Use it alongside sitemap validation, sitemap analysis, crawlability checks, and indexability checks to build a more complete technical SEO workflow.