
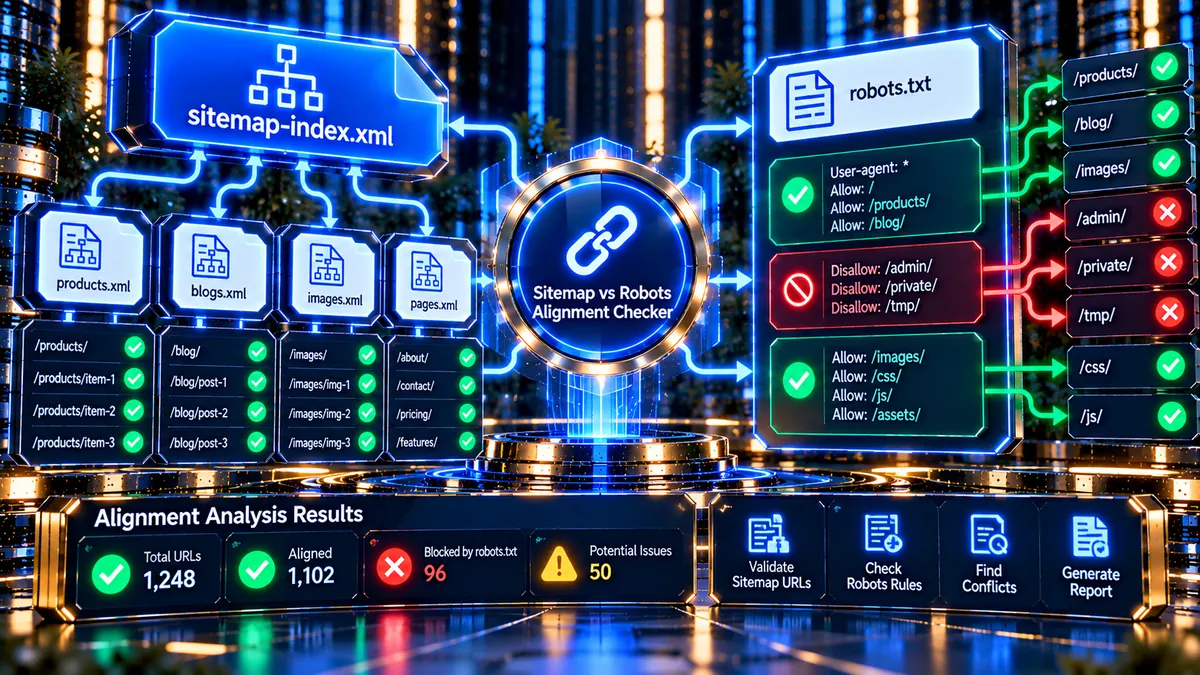
The Sitemap vs Robots Alignment Checker is a technical SEO diagnostic tool that compares URLs discovered through your XML sitemap structure with the crawling rules defined in robots.txt. It can process sitemap indexes, expand child sitemaps, extract URL nodes, compile Allow and Disallow rules, and identify sitemap URLs that conflict with effective robots.txt restrictions. This makes it easier to detect crawl-control problems that may otherwise remain hidden inside large sitemap architectures.
Sitemap vs Robots Alignment Checker
Cross-reference sitemap URLs against active robots.txt directives, recursively expand sitemap indexes, detect blocked sitemap nodes, measure alignment cleanliness, and document remediation without paid APIs, proxies or VPS infrastructure.
Cross-Reference Alignment Matrix
Every harvested sitemap URL is matched against applicable robots.txt Allow/Disallow patterns.
| # | Evaluated URL Path | Applicable Robots Directives | Conflict Status Rule | Recommended Remediation |
|---|
What Is a Sitemap vs Robots Alignment Checker?
A Sitemap vs Robots Alignment Checker compares two important technical SEO resources:
- Your XML sitemap structure.
- Your robots.txt crawling rules.
XML sitemaps help search engines discover URLs. The robots.txt file communicates crawler access restrictions for URL paths.
These resources have different purposes, but they can create technical conflicts.
For example, a sitemap may contain:
while robots.txt contains:
Disallow: /products/
The product URL is therefore present in the sitemap while its path is blocked by the applicable robots rule.
PKCapra’s Sitemap vs Robots Alignment Checker is designed to identify this type of conflict at URL level.
Why Sitemap and Robots.txt Alignment Matters
Search engines use sitemap information and crawler access rules for different parts of the discovery and crawling process.
A sitemap can identify URLs that should be discovered, while robots.txt can restrict crawler access to specific paths.
Common alignment problems include:
- Important URLs listed in a sitemap but blocked by robots.txt.
- Broad Disallow rules affecting entire content directories.
- Sitemap indexes containing child sitemap files that are not fully evaluated.
- Overlapping Allow and Disallow rules.
- Incorrectly parsed robots.txt directives.
- Old sitemap URLs remaining after a website structure changes.
- Child sitemap resources that are unavailable or incorrectly configured.
A URL should therefore be reviewed in the context of both its sitemap presence and its crawler-access configuration.
How the Sitemap vs Robots Alignment Checker Works
PKCapra processes the sitemap and robots.txt datasets together through a structured technical audit.
The workflow includes:
- Fetching the supplied sitemap resource.
- Inspecting the XML root element.
- Detecting whether the resource is a sitemap index or URL set.
- Expanding referenced child sitemap resources.
- Processing nested sitemap indexes where applicable.
- Extracting URL nodes from the discovered sitemap files.
- Combining and deduplicating the discovered URLs.
- Fetching robots.txt.
- Parsing User-agent, Allow, Disallow and Sitemap directives.
- Compiling active crawler rules.
- Processing supported wildcard and terminal path patterns.
- Comparing sitemap URLs against the effective robots rules.
- Detecting URLs affected by blocking rules.
- Building the alignment dashboard and diagnostic report.
This allows the audit to evaluate the actual URL dataset discovered through the sitemap hierarchy rather than only checking whether the root sitemap file exists.
Recursive Sitemap Index Analysis
Large websites often use a sitemap index instead of placing every URL inside a single XML sitemap.
A sitemap index can reference multiple child sitemap files, for example:
- Post sitemap.
- Page sitemap.
- Product sitemap.
- Category sitemap.
- Image sitemap.
- Video sitemap.
- News sitemap.
The root sitemap index contains references to these resources rather than the final URL nodes.
The Sitemap vs Robots Alignment Checker detects the sitemap index structure and continues into its child sitemap resources.
Deep Sitemap Index Expansion
When the supplied XML contains a <sitemapindex> element, the checker does not stop at the root document.
Instead, it follows the sitemap hierarchy and processes the referenced child resources.
The processing structure can look like:
Root Sitemap Index → Child Sitemap → URL Set → URL Nodes
If another sitemap index is discovered inside the hierarchy, processing can continue through the nested structure:
Root Sitemap Index → Child Sitemap Index → Nested Sitemap → URL Set → URL Nodes
The final audit dataset therefore represents the combined URL nodes discovered throughout the sitemap structure.
Total Evaluated Map Assets
The Total Evaluated Map Assets metric represents the combined unique URL nodes harvested from the sitemap processing operation.
This is particularly useful when a website uses multiple child sitemaps.
For example, if a sitemap index references separate product, page and post sitemaps, the URL nodes discovered across those resources can be combined into the same alignment audit.
This provides a more meaningful evaluation scope than simply counting the root sitemap index file.
Robots.txt Blueprint Parser
The robots.txt parser processes the file line by line and separates crawler access directives from sitemap declarations.
The main directives used by the alignment engine include:
User-agentAllowDisallowSitemap
Directive matching is handled case-insensitively.
For example, these forms can be recognized as the same directive type:
User-agent:
USER-AGENT:
user-agent:
The same principle applies to Allow, Disallow and Sitemap directives.
Sitemap Directives Inside Robots.txt
A robots.txt file can contain a Sitemap declaration such as:
Sitemap: https://example.com/sitemap.xml
The Sitemap directive identifies a sitemap resource. It is not a crawler Allow or Disallow rule.
PKCapra therefore treats Sitemap declarations separately from access-control directives.
This prevents valid Sitemap lines from being incorrectly classified as unsupported crawler rules.
Active Robots Rule Compilation
After parsing robots.txt, the checker compiles active Allow and Disallow directives into its internal path-matching structure.
The dashboard reports the number of active rules successfully compiled.
This provides an immediate indication of whether the robots.txt file contains usable crawler rules for the alignment analysis.
The compiled rules are then evaluated against the URLs collected from the sitemap structure.
Allow and Disallow Rules
Robots.txt can contain both Allow and Disallow rules.
For example:
User-agent: *
Disallow: /private/
Allow: /private/public/
These rules overlap because the Allow path exists inside the broader Disallow path.
The effective result depends on the applicable matching rules and their specificity.
The alignment engine evaluates the path rules rather than performing a simple text search.
Wildcard Robots.txt Rules
Robots.txt configurations can contain wildcard patterns.
For example:
Disallow: /*?session=
Wildcard patterns can affect multiple URL variations.
The checker compiles supported wildcard patterns into its path-matching logic so that sitemap URLs can be evaluated against the applicable robots rules.
This is especially useful for websites that use query parameters or dynamic URL structures.
Terminal $ Path Matching
The checker also supports terminal $ matching.
For example:
Disallow: /private$
The $ marker represents the end of the matching pattern.
This is different from a simple directory-prefix rule and therefore needs to be interpreted correctly during robots rule compilation.
Contradiction Alignment Faults
The Contradiction Alignment Faults metric identifies sitemap URLs that match an effective robots.txt blocking rule.
For example:
Sitemap URL:
Robots rule:
Disallow: /private/
The sitemap identifies the URL while the robots rule blocks the matching path.
The URL can therefore be reported as an alignment contradiction for technical review.
System Network Handshake
The System Network Handshake card shows the HTTP response status for the sitemap and robots.txt resources used during the audit.
A successful result may show:
- Sitemap HTTP 200.
- robots.txt HTTP 200.
This separates network accessibility from alignment analysis.
A sitemap returning HTTP 200 only confirms that the sitemap resource was successfully retrieved. It does not mean that every URL contained inside the sitemap is allowed by robots.txt.
Overall Synchronization Verdict
After the sitemap URL dataset has been evaluated against the compiled robots rules, the checker produces an overall synchronization result.
When no sitemap URLs are found to conflict with effective blocking rules, the dashboard can display:
GREEN — COMPLIANT
When sitemap URLs are found to conflict with effective blocking rules, the dashboard can display:
RED — CRITICAL MISALIGNMENT DETECTED
The verdict applies to the sitemap URLs actually evaluated during the audit.
Sitemap Alignment Matrix
The detailed results matrix provides URL-level information about the relationship between sitemap URLs and robots.txt rules.
Depending on the audit result, the matrix can identify:
- Sitemap URL or path.
- Applicable robots directive.
- Matching Allow or Disallow rule.
- Conflict status.
- Recommended remediation direction.
This makes it easier to investigate individual URLs instead of manually comparing large XML sitemap and robots.txt files.
Common Sitemap and Robots.txt Conflicts
Sitemap URL Blocked by Disallow
An important URL may appear in the sitemap while a broader directory is blocked.
For example:
Disallow: /products/
while the sitemap contains:
The configuration should be reviewed to determine whether the blocking behavior is intentional.
Broad Disallow Rules
A broad Disallow rule can affect many sitemap URLs.
For example:
Disallow: /blog/
can affect URLs under the entire /blog/ path.
Overlapping Allow and Disallow Rules
An Allow rule can create an exception inside a broader Disallow path.
For example:
Disallow: /private/
Allow: /private/public/
These overlapping rules need to be evaluated according to the applicable path-matching behavior.
Sitemap URLs That Should No Longer Be Published
A sitemap may contain URLs that are no longer part of the intended website architecture.
In this situation, the correct action may involve reviewing the sitemap rather than simply changing robots.txt.
Incomplete Sitemap Index Processing
A sitemap index can contain many child resources.
If only the root index is inspected, the actual URL nodes contained in those child files may never be evaluated.
Recursive processing helps expose the deeper sitemap URL structure.
Sitemap vs Robots Alignment and Crawlability
Sitemap alignment and crawlability are related but different technical SEO concepts.
A sitemap communicates URL discovery information.
robots.txt communicates crawler access rules.
For broader crawler testing, use the Crawlability Checker alongside this tool.
The two analyses can help separate sitemap configuration issues from broader crawler-access problems.
Sitemap vs Robots Alignment and Indexability
Robots.txt is not the only technical factor affecting indexability.
A broader indexability review can include:
- Meta robots directives.
- X-Robots-Tag headers.
- Canonical URLs.
- HTTP status codes.
- Redirect behavior.
- Page accessibility.
The Indexability Checker can be used for a broader indexability-focused review.
Sitemap vs Robots Alignment and XML Sitemap Analysis
The XML Sitemap Analyzer focuses on XML sitemap analysis and sitemap-level information.
The Sitemap vs Robots Alignment Checker has a different purpose.
Its primary relationship is:
Sitemap URLs → Robots Rules → Alignment Analysis
Using both tools can provide a broader sitemap diagnostic workflow.
How to Use the Sitemap vs Robots Alignment Checker
Step 1: Enter Your Domain or Sitemap
Enter the website domain or the direct XML sitemap URL supported by the tool.
Step 2: Retrieve Sitemap and Robots Resources
The checker retrieves the sitemap resource and obtains robots.txt information required for the alignment analysis.
Step 3: Detect the Sitemap Structure
The XML root is inspected to determine whether the resource is a URL set or sitemap index.
Step 4: Expand Child Sitemaps
If a sitemap index is detected, the checker follows its child sitemap locations and continues through the sitemap structure.
Step 5: Collect URL Nodes
The final URL nodes are collected into the combined audit dataset.
Duplicate URL entries are removed from the evaluation set.
Step 6: Parse robots.txt
The checker reads robots.txt and identifies User-agent, Allow, Disallow and Sitemap directives.
Step 7: Compile Active Rules
Allow and Disallow directives are converted into the internal path-matching structure.
Step 8: Cross-Reference the URL Dataset
The sitemap URLs are compared against the effective robots rules.
Step 9: Review Alignment Faults
Any sitemap URL affected by an effective blocking rule can be reviewed through the dashboard and matrix.
Step 10: Export the Results
The Copy JSON Data and Download PDF Report options can be used to retain the completed audit results.
JSON Audit Data
The Copy JSON Data feature provides structured information from the completed alignment audit.
Depending on the audit, the dataset can include:
- Sitemap HTTP status.
- robots.txt HTTP status.
- Sitemap asset counts.
- Recursive sitemap information.
- Evaluated URL counts.
- Active robots rule counts.
- Alignment faults.
- Sitemap directives.
- Diagnostic messages.
The JSON output can be useful for technical SEO documentation, developer troubleshooting and QA workflows.
PDF Audit Report
The Download PDF Report option provides a report-friendly version of the completed audit.
The report can be useful for:
- Technical SEO audits.
- Developer handoffs.
- Robots.txt troubleshooting.
- Sitemap architecture reviews.
- Website migrations.
- Configuration QA.
- Before-and-after technical comparisons.
Important Audit Scope Limitation
The Sitemap vs Robots Alignment Checker evaluates URLs discovered through the supplied sitemap structure.
It does not perform a complete website crawl to discover every URL that exists on the website but is absent from the sitemap.
Therefore, the alignment result should be interpreted as:
Sitemap URL dataset vs robots.txt rules
rather than:
Every URL on the website vs robots.txt rules
A separate crawl-based process is required when the objective is to discover unlisted or orphan URLs.
Sitemap and Robots Alignment for Large Websites
Large websites often distribute their URLs across multiple sitemap files.
Examples include:
- Product sitemap files.
- Blog sitemap files.
- Page sitemap files.
- Category sitemap files.
- Image sitemap files.
- Video sitemap files.
- News sitemap files.
A sitemap index can connect these resources.
Recursive sitemap processing is therefore especially useful when auditing larger websites because the root sitemap index may not contain the final URL nodes.
Sitemap and Robots Alignment for E-commerce Websites
E-commerce websites can contain thousands of product, category and informational URLs.
Typical sitemap architectures can include separate resources for:
- Products.
- Categories.
- Pages.
- Blog content.
At the same time, robots.txt may contain rules intended to control:
- Search pages.
- Filter URLs.
- Internal parameters.
- Private areas.
- Administrative paths.
A sitemap-to-robots comparison can help identify situations where important sitemap URLs are affected by broader crawler restrictions.
Sitemap and Robots Alignment for WordPress Websites
WordPress websites can contain multiple sitemap resources depending on the site’s configuration and installed SEO systems.
A website may publish sitemap resources for:
- Posts.
- Pages.
- Taxonomies.
- Authors.
- Custom content types.
When these resources are connected through a sitemap index, recursive processing allows the URL nodes inside the child resources to be included in the alignment audit.
Technical SEO Investigation Workflow
A practical technical workflow can include:
- Check the sitemap structure.
- Expand sitemap indexes.
- Review the evaluated URL count.
- Parse robots.txt.
- Review active Allow and Disallow rules.
- Identify contradiction alignment faults.
- Review affected URLs.
- Verify whether the blocking behavior is intentional.
- Check related crawlability and indexability signals.
- Re-run the audit after making configuration changes.
For a broader website assessment, use the Technical SEO Checker and Full SEO Site Audit alongside this tool.
Sitemap vs Robots Alignment During Website Migrations
Website migrations can change both sitemap structures and robots.txt rules.
Before and after a migration, technical teams can review:
- Sitemap index structure.
- Child sitemap locations.
- URL counts.
- robots.txt directives.
- Directory restrictions.
- Important sitemap URLs.
- Alignment contradictions.
This can help identify configuration changes that may otherwise remain hidden inside a large XML sitemap architecture.
Best Practices When an Alignment Fault Is Found
When a sitemap URL is reported as blocked, review the configuration before changing anything.
Check:
- Whether the URL should be crawlable.
- Whether the Disallow rule is intentional.
- Whether the rule is broader than intended.
- Whether a more specific Allow rule applies.
- Whether the sitemap URL is current.
- Whether the URL returns the expected HTTP status.
- Whether canonical and indexability signals are configured correctly.
Do not automatically remove a robots.txt restriction simply because a URL appears in a sitemap.
The intended crawl architecture should be understood first.
Frequently Asked Questions
What does the Sitemap vs Robots Alignment Checker do?
It compares URLs discovered through XML sitemaps with the effective Allow and Disallow rules defined in robots.txt.
Can the tool analyze a sitemap index?
Yes. The checker detects sitemap indexes and processes their referenced child sitemap resources.
Does it inspect URLs inside child sitemaps?
Yes. URL nodes discovered inside child sitemap files are added to the combined audit dataset.
Can it process nested sitemap indexes?
Yes. The recursive sitemap processing architecture can continue when additional sitemap index structures are discovered.
Does it recognize Sitemap directives in robots.txt?
Yes. Sitemap directives are parsed separately from crawler access rules.
Is robots.txt directive matching case-sensitive?
The main directive names are handled case-insensitively.
Does the checker support Allow rules?
Yes. Allow rules are compiled and evaluated alongside Disallow rules.
Does it support wildcard robots.txt patterns?
Yes. Supported wildcard patterns are processed by the robots rule matching engine.
Does it support terminal $ matching?
Yes. Applicable terminal $ patterns are supported during rule evaluation.
What is a contradiction alignment fault?
It is a sitemap URL that matches an effective robots.txt blocking rule during the audit.
Can a sitemap return HTTP 200 and still contain alignment faults?
Yes. HTTP 200 confirms that the sitemap resource was retrieved successfully. Individual URLs inside the sitemap can still conflict with robots.txt.
Does the checker crawl every URL on the website?
No. It evaluates URLs discovered through the supplied sitemap structure. It does not claim to discover every URL that exists outside the sitemap.
Why is recursive sitemap processing important?
A sitemap index can contain multiple child sitemap files. Recursive processing allows the checker to reach the actual URL nodes inside those files.
Can I export the audit?
Yes. The tool provides Copy JSON Data and Download PDF Report functionality.
What should I do if an important sitemap URL is blocked?
First confirm whether the blocking rule is intentional. Then review the applicable robots.txt rule, its scope, any overlapping Allow rule, and the intended crawl architecture before changing the configuration.
Use PKCapra for Technical SEO Analysis
The Sitemap vs Robots Alignment Checker provides a focused way to compare sitemap URL discovery with robots.txt crawler restrictions.
For broader technical SEO analysis, combine it with the Technical SEO Checker, Crawlability Checker, Indexability Checker, XML Sitemap Analyzer and Full SEO Site Audit.
Enter your sitemap or website domain, let the checker process the sitemap structure, review the compiled robots.txt rules, and inspect the alignment matrix to identify technical crawling conflicts.