
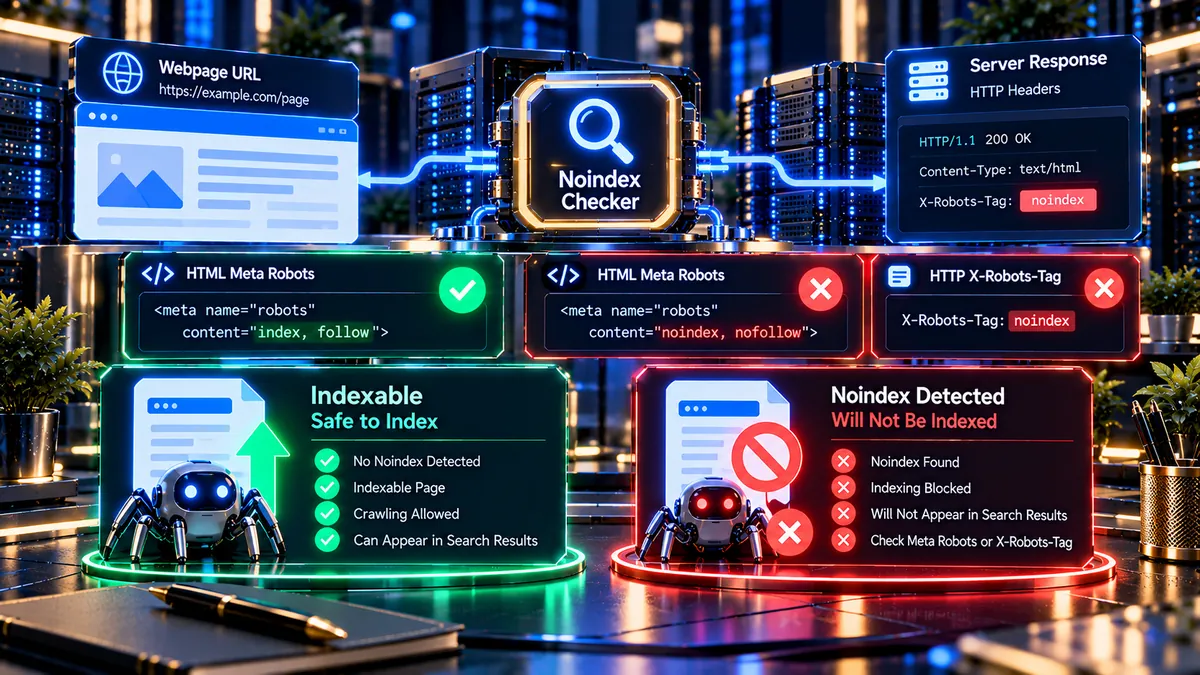
Check whether a webpage contains a noindex directive with PKCapra’s free Noindex Checker. Analyze meta robots tags, Googlebot directives, and HTTP X-Robots-Tag headers to determine whether a page is configured to remain indexable or blocked from search indexing.
Noindex Checker
Check HTML meta robots directives and HTTP X-Robots-Tag headers to determine whether a public URL is blocked from search engine indexing.
The result reflects the response returned to the local WordPress server at scan time. Meta robots directives are read from the HTML head, while X-Robots-Tag is inspected from the raw HTTP response headers.
Only submit public URLs that you are authorized to analyze. The checker uses the native WordPress HTTP engine with a robust local cURL fallback and does not require a paid proxy, premium API, or VPS.
What Is a Noindex Checker?
A Noindex Checker is a technical SEO tool that checks whether a webpage contains instructions telling search engines not to index the URL.
A noindex directive can appear in the HTML through a robots meta tag or in the HTTP response through an X-Robots-Tag header. These signals can affect whether search engines are allowed to include a page in their search index.
PKCapra’s free Noindex Checker examines both areas in one scan. It shows the detected directives, HTTP response status, and an overall indexation clearance so you can quickly identify whether a page appears configured for indexing or contains an active noindex restriction.
Why Check for Noindex Directives?
A noindex directive can be intentional or accidental. Developers may use it for private pages, staging environments, duplicate URLs, temporary pages, internal search results, or content that should not appear in search results.
Problems can occur when a noindex directive remains on a page that is supposed to receive organic search traffic.
A technical SEO check can therefore help you identify unexpected indexing restrictions before investigating rankings, traffic changes, migrations, or content visibility issues.
For broader indexing analysis, you can also use the Indexability Checker.
How Does the Noindex Checker Work?
PKCapra starts by requesting the URL you provide and examining the HTTP response and returned HTML.
The checker then inspects the HTML head for robots-related meta tags and examines the response headers for X-Robots-Tag directives.
The tool looks for indexing restrictions such as noindex and none. It also reports relevant directives such as noimageindex so that the result provides useful technical context rather than treating every robots directive as identical.
The final dashboard combines these signals into a clear indexation status.
What Is the Robots Meta Tag?
The robots meta tag is an HTML element that can communicate crawler instructions for a webpage.
A common example is a robots directive containing noindex. This tells supported search engines that the page should not be included in their index.
A page may also contain a Google-specific directive using googlebot. PKCapra checks both the general robots declaration and Googlebot-specific declarations during the scan.
Because these directives are part of the page HTML, inspecting the actual response source can reveal restrictions that are not obvious from the visible page.
What Is X-Robots-Tag?
X-Robots-Tag is an HTTP response header used to communicate robots directives outside the HTML document.
This makes it especially useful for resources where HTML meta tags are not available, including some non-HTML responses and server-generated resources.
A response can contain an X-Robots-Tag directive that includes noindex. PKCapra checks the raw response headers so this server-level signal is not missed during the audit.
Checking both HTML and HTTP headers is important because a page can appear normal in the browser while still returning an indexing restriction through its response headers.
Noindex Checker Results
After the scan completes, PKCapra presents the findings in a visual technical SEO dashboard.
HTML Meta Robots Status
This status shows whether a relevant robots meta directive was detected in the page HTML.
A clean result indicates that the checker did not find an active noindex or equivalent page-level blocking directive in the inspected robots metadata.
HTTP X-Robots Header Status
This card reports whether the HTTP response contains an X-Robots-Tag indexing restriction.
This is useful when indexing controls are being added at the server, CDN, framework, or application level rather than directly inside the HTML.
Overall Indexation Clearance
The overall clearance combines the detected indexing signals and shows whether the scanned response contains an active noindex restriction.
A green result indicates that the checker did not detect a blocking noindex or none directive in the inspected signals. A red result indicates that an indexing restriction was detected and should be reviewed.
Noindex vs Indexable
An indexable page is not explicitly blocked from indexing by the noindex signals inspected by this tool.
A page with an active noindex directive is configured to prevent indexing by search engines that support and process that directive.
This distinction is important during technical SEO audits because a page can be publicly accessible while still carrying an instruction not to appear in search results.
The Noindex Checker focuses specifically on these indexing directives. It does not treat a successful HTTP response alone as proof that a page is eligible for indexing.
What Does “Noindex Active” Mean?
Noindex Active means that PKCapra detected an indexing restriction in the inspected HTML robots directives or HTTP X-Robots-Tag response headers.
The finding should be compared with the intended purpose of the page.
For example, noindex may be completely intentional for a private utility page, temporary URL, staging environment, duplicate page, or other content that should not appear in organic search.
If the URL is intended to attract organic traffic, investigate the directive before removing it.
Noindex and the Googlebot Meta Tag
Websites can provide crawler instructions specifically for Googlebot through a Googlebot robots meta tag.
PKCapra checks Googlebot-specific metadata as part of its noindex analysis so that a general robots declaration is not the only signal considered.
This is particularly useful when a website uses different crawler directives for different search engines or automated agents.
What Does the “None” Directive Mean?
The none robots directive represents a combination of restrictions that includes noindex and nofollow behavior for supported crawlers.
For a Noindex Checker, detecting none is important because it contains a noindex component.
PKCapra therefore treats an applicable none directive as an indexation blocking signal rather than reporting the page as clean.
What Is Noimageindex?
The noimageindex directive is different from a general noindex instruction. It concerns image indexing rather than simply blocking the webpage itself from the search index.
PKCapra identifies noimageindex as a separate technical directive so the report can provide more context about what was actually found.
Do not assume that every robots directive has the same effect. Review the exact directive displayed in the findings before changing your SEO configuration.
Meta Robots vs X-Robots-Tag
Meta robots directives are delivered inside the HTML document. X-Robots-Tag directives are delivered through HTTP response headers.
Both mechanisms can communicate crawler instructions, but they are implemented at different layers.
This difference matters during troubleshooting. If the HTML looks clean but the checker reports an X-Robots restriction, the indexing instruction may be coming from the web server, CDN, application framework, security layer, or another HTTP response component.
Checking both sources gives you a more complete view of the URL’s indexing configuration.
Noindex and Robots.txt Are Different
A robots.txt rule and a noindex directive are not the same mechanism.
Robots.txt primarily controls whether crawlers are allowed to request URLs, while noindex communicates an indexing preference through page or HTTP metadata.
For this reason, a complete technical SEO investigation may require checking both crawl controls and indexing directives.
Use the Robots.txt Analyzer when you need to inspect robots.txt rules as part of the investigation.
Noindex and Indexability
Indexability is broader than a single noindex directive.
A page can have a clean robots meta tag while other technical conditions still affect crawling, rendering, accessibility, canonicalization, or indexing.
The Indexability Checker provides a broader indexability-oriented review, while the Noindex Checker focuses specifically on noindex-related signals.
Using both tools can help separate a direct noindex problem from a wider technical SEO issue.
Noindex During Website Migrations
Temporary noindex directives are sometimes used during development and website migrations.
The risk appears when those temporary restrictions remain after the migration is complete.
Important production URLs should be checked after major migrations, domain changes, HTTPS transitions, URL restructuring, and CMS changes.
A migration review should also consider redirects, canonicals, robots.txt, sitemaps, and HTTP responses.
For redirect-path analysis, use the Redirect Chain Checker.
For canonical relationships, use the Canonical URL Checker.
Noindex and Canonical Tags
Noindex and canonical tags serve different purposes and should not be treated as interchangeable controls.
A canonical tag communicates a preferred URL relationship. A noindex directive communicates an indexing restriction.
If a page contains both signals, investigate why both are present and whether they match the intended site architecture.
For detailed canonical inspection, use the Canonical URL Checker.
Noindex and HTTP Status Codes
The HTTP response status provides important context during a noindex audit.
A successful HTTP response does not automatically mean that the page is indexable. The response may still contain an X-Robots-Tag noindex directive or the HTML may contain a robots meta restriction.
Likewise, a server error or access restriction may prevent a complete noindex analysis.
PKCapra displays the HTTP response information alongside the indexing findings so you can distinguish an indexing directive from a network or server response problem.
For a dedicated HTTP response investigation, use the HTTP Status Checker.
How to Use the Noindex Checker
1. Enter the URL
Enter the complete public HTTP or HTTPS URL you want to inspect.
2. Start the Analysis
Click the check button to start the server-side URL analysis.
3. Review the Meta Robots Status
Check whether the HTML contains robots or Googlebot directives that include an indexing restriction.
4. Review the X-Robots-Tag Status
Inspect the HTTP header result to determine whether the server response contains an X-Robots-Tag noindex instruction.
5. Check the Overall Clearance
Use the overall indexation clearance card to understand whether an active noindex restriction was detected.
6. Read the Technical Findings
Review the exact directive, source, HTTP status, and supporting information before making any production change.
7. Export the Report
Use Copy JSON when you need structured audit data. Use Download PDF Report when you need a visual record for documentation, client reporting, or technical SEO review.
How to Fix an Unexpected Noindex Directive
Start by identifying exactly where the directive was detected.
If it appears in a robots meta tag, inspect the page template, SEO plugin settings, CMS configuration, or custom HTML responsible for generating the tag.
If it appears in an X-Robots-Tag header, inspect the web server, CDN, reverse proxy, application framework, or other HTTP-layer configuration.
Do not remove a noindex directive simply because it appears in a scan. First confirm that the URL is intended to be indexed.
After making a configuration change, run the Noindex Checker again and compare the new response with the previous report.
Noindex Problems on WordPress Websites
WordPress websites can generate robots directives through several layers, including SEO plugins, theme templates, custom code, page-level settings, and server configuration.
A noindex finding should therefore be traced back to its source instead of being fixed blindly.
If the page is intended to rank, inspect the page-level SEO settings first. Then review broader site configuration if the directive remains present.
For a wider WordPress technical review, use the Technical SEO Checker.
Noindex Checking for Staging Websites
Development and staging environments commonly use noindex directives to reduce the chance of test pages appearing in search engines.
That configuration can be useful while a site is under development, but it should be reviewed carefully before production launch.
After moving a website from staging to production, check important URLs to confirm that temporary indexing restrictions were removed where appropriate.
Noindex Checking After a Website Redesign
A redesign can change page templates, SEO plugin settings, metadata, server rules, and rendering behavior.
These changes can introduce unexpected indexing directives even when the visible page looks correct.
Run noindex checks on important pages after a redesign and compare the results with your intended indexing policy.
For a wider site-level review, use the Full SEO Site Audit.
Noindex Checking for SEO Audits
Noindex detection is a useful component of a technical SEO audit because indexing restrictions can directly affect whether important URLs can appear in search.
Review representative pages from important templates, categories, landing pages, articles, product pages, and other indexable content types.
When a problem is discovered, document the exact URL, directive source, HTTP response, and intended indexing state.
This creates a clearer remediation path than simply reporting that a page is not visible in search.
Noindex Checker vs Indexability Checker
The Noindex Checker is focused on detecting noindex-related robots directives in HTML and HTTP response headers.
The Indexability Checker covers a broader set of indexability signals and is useful when you need more than a dedicated noindex inspection.
Use the Noindex Checker when you want a fast, focused answer about noindex signals. Use the Indexability Checker when you need a wider technical indexability assessment.
Noindex Checker vs Full SEO Site Audit
The Noindex Checker is designed for a specific technical question: does the inspected response contain an indexing restriction?
A full SEO audit covers a much wider range of technical, on-page, crawl, performance, metadata, links, and other website signals.
Use the Full SEO Site Audit when you need a broader website assessment rather than a single URL noindex check.
Free Noindex Checker
PKCapra provides the Noindex Checker as a free technical SEO tool. It is designed to perform the analysis directly through the WordPress environment without requiring a premium SEO API, paid proxy service, or VPS.
The tool checks the target response, analyzes HTML robots metadata, inspects X-Robots-Tag headers, and presents the result through a visual dashboard.
The report can also be copied as structured JSON or saved as a PDF for technical documentation.
Frequently Asked Questions
What is a noindex tag?
A noindex directive tells supported search engines not to include the affected URL in their search index.
Where can a noindex directive appear?
It can appear in an HTML robots meta tag or through an HTTP X-Robots-Tag response header.
Does PKCapra check X-Robots-Tag?
Yes. The Noindex Checker inspects the raw HTTP response headers for X-Robots-Tag indexing directives.
Does the checker inspect Googlebot directives?
Yes. PKCapra checks Googlebot-specific robots metadata in addition to the general robots meta tag.
What does “Noindex Active” mean?
It means the checker detected an indexing restriction such as noindex or none in the inspected HTML or HTTP response headers.
What does “Indexable” mean in the checker?
It means the checker did not detect an active noindex or none directive in the inspected robots metadata and X-Robots-Tag response headers.
Does a green Noindex Checker result guarantee Google indexing?
No. A clean noindex result means that this specific indexing restriction was not detected. Other technical, content, crawling, quality, canonical, or indexing factors can still affect search visibility.
Is noimageindex the same as noindex?
No. Noimageindex is an image-indexing directive and should not automatically be interpreted as a complete webpage noindex instruction.
Can robots.txt cause the same result as noindex?
Robots.txt and noindex are different mechanisms. Robots.txt controls crawler access, while noindex communicates an indexing restriction through supported robots metadata or HTTP headers.
Can WordPress accidentally add noindex?
Yes. WordPress configurations, SEO plugins, templates, custom code, staging settings, and server-level rules can contribute to robots directives. The exact source should be identified before changing the configuration.
Can I check a staging website?
The URL must be publicly reachable by the server performing the check. Private or authentication-protected environments may not be accessible to the checker.
Does the Noindex Checker use a paid API?
No. PKCapra’s Noindex Checker is designed for free local execution through the WordPress environment without a premium SEO API.
Can I export the result?
Yes. The dashboard provides Copy JSON and Download PDF Report options for saving the analysis.
Should I remove every noindex directive?
No. Noindex can be intentional. Always confirm the intended indexing state of the URL before changing a directive.
Final Thoughts
A page can look completely normal in a browser while carrying a noindex instruction in its HTML or HTTP response.
PKCapra’s Noindex Checker brings these signals together in one focused technical SEO report. It checks robots metadata, Googlebot directives, X-Robots-Tag headers, HTTP response information, and the overall indexation clearance.
Use it when troubleshooting unexpected search visibility problems, reviewing WordPress configurations, validating migrations, checking redesigned pages, or auditing important URLs.
For a broader technical investigation, combine the Noindex Checker with the Indexability Checker, Robots.txt Analyzer, Canonical URL Checker, Technical SEO Checker, and Full SEO Site Audit.
Only analyze public URLs that you are authorized to inspect, and review technical findings carefully before changing production indexing configuration.