
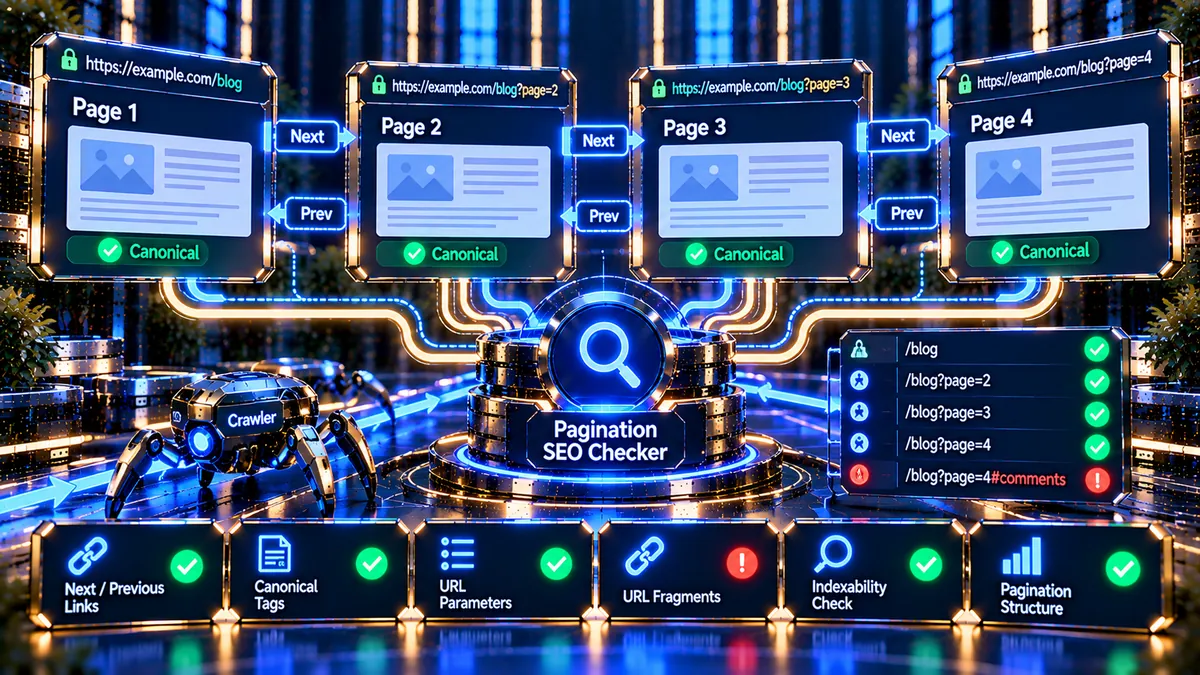
Pagination can look simple on the surface, but the way a website connects pages in a long category, archive, product listing, blog, or results sequence can affect how search engines discover and understand that content.
PKCapra’s Pagination SEO Checker analyzes a live HTML page and checks the pagination signals that matter for crawlability, URL structure, canonicalization, indexation directives, and navigation between paginated pages.
Enter a page URL above to inspect its pagination implementation and identify signals that may need attention.
Pagination SEO Diagnostic
Pagination Signals
Detected Pagination URLs
Report Actions
What Does a Pagination SEO Checker Do?
A Pagination SEO Checker examines how a page communicates its relationship with other pages in a paginated sequence.
For example, a category may contain hundreds of products but display only 24 products per page:
/category/shoes//category/shoes/page/2//category/shoes/page/3/
Or a website may use query parameters:
/products?page=2/products?page=3
The important SEO question is not simply whether pagination exists. It is whether the search engine can discover the additional pages, whether those pages have meaningful URLs, and whether canonical and indexing signals are consistent with the site’s intended structure.
PKCapra’s Pagination SEO Checker inspects these signals from the HTML response and presents them in a single diagnostic report.
What Does PKCapra’s Pagination SEO Checker Check?
The checker analyzes several pagination-related signals.
HTTP Response
The tool reports the HTTP status returned by the analyzed page.
A successful response is important because a pagination page that returns an HTTP error cannot reliably serve its intended content to users or crawlers.
The checker flags HTTP responses at 400 or above as an issue.
Detected Pagination Page
The tool attempts to identify a page number from common pagination URL patterns.
It recognizes patterns such as:
?page=2?paged=2?pagenum=2?page_num=2?page-number=2/page/2//p/2/
This helps determine whether the URL itself identifies a separate page in a pagination sequence.
Crawlable Pagination Links
The checker looks at HTML <a href> elements and searches for pagination-related navigation.
It can identify:
- Next links
- Previous links
- Older links
- Newer links
- Page-number URLs
- Pagination URLs exposed through anchor elements
This distinction matters because a visually working pagination interface is not necessarily the same thing as crawlable HTML navigation.
Next and Previous Navigation
The report separately identifies detected Next and Previous URLs.
For example, it can recognize navigation based on:
- Link text such as “Next” or “Previous”
- ARIA labels
- Relevant link attributes
- Pagination-related URL structures
The tool shows the detected URLs in the report so you can inspect the actual navigation being exposed by the page.
Canonical URL
The checker reads the page’s rel="canonical" element and reports the detected canonical URL.
It also compares the canonical target with the current page.
This is particularly important for paginated pages because a pagination page should not automatically be treated as a duplicate of page one simply because it belongs to the same collection.
Google’s current pagination documentation recommends giving each paginated page its own URL and not using the first page as the canonical URL for every page in the sequence. :contentReference[oaicite:1]{index=1}
Self-Referencing Canonical
The tool checks whether the canonical URL points back to the current page after URL normalization.
For example, if the analyzed URL is:
and the canonical also points to that same page, the checker identifies the canonical as self-referencing.
This provides a useful diagnostic signal when reviewing paginated pages individually.
Pagination Canonicalized to Page One
One of the more important checks is whether a detected paginated page points its canonical back to page one.
For example:
with a canonical pointing to:
The checker flags this pattern as a high-priority pagination issue because it can conflict with the intended separation of paginated URLs.
Google specifically recommends that each page in a paginated sequence have its own canonical URL rather than making page one the canonical for all pages. :contentReference[oaicite:2]{index=2}
Meta Robots Noindex
The checker searches the page for a noindex directive in the robots meta element.
If a paginated page contains noindex, the report highlights it because the directive can prevent that URL from being eligible for indexing.
Whether noindex is appropriate depends on the site’s intended architecture. The important point is to understand what the directive is doing before treating it as an automatic error.
X-Robots-Tag Noindex
The tool also checks the HTTP response for an X-Robots-Tag containing noindex.
This is different from a normal HTML meta robots directive because it is supplied through the HTTP response headers.
A paginated page affected by either form of noindex should be reviewed against the site’s indexing strategy.
Fragment-Based Pagination
The checker looks for pagination links that use URL fragments such as:
#page=2
or similar page-number fragment patterns.
This matters because URL fragments are not separate server-requested URLs in the same way as normal path or query-string URLs.
Google’s pagination guidance specifically recommends using unique URLs rather than fragment identifiers for paginated pages. :contentReference[oaicite:3]{index=3}
Legacy rel=”next” and rel=”prev”
The checker detects legacy rel="next" and rel="prev" annotations when they are present.
The report marks these as a review item rather than treating their presence as a critical failure.
Google no longer uses these annotations for pagination, although other search engines may still process them. :contentReference[oaicite:4]{index=4}
Load More and Infinite Scroll Signals
The checker also looks for buttons and elements that contain recognizable labels such as:
- Load More
- Show More
- Load Next
- Infinite Scroll
This is a heuristic signal, not a complete JavaScript rendering test.
A page may visually load additional content through JavaScript while exposing few or no crawlable pagination URLs in the initial HTML.
Google’s documentation notes that Googlebot generally discovers URLs through crawlable links and does not normally interact with buttons that require user actions to update page content. :contentReference[oaicite:5]{index=5}
Why Pagination Matters for SEO
Pagination is commonly used when a website has more content than it is practical to display on one page.
Typical examples include:
- Ecommerce product categories
- Blog archives
- News archives
- Search results
- Forum threads
- Review listings
- Product collections
- Large resource directories
Breaking a large collection into smaller pages can improve usability and page performance. But the SEO implementation still needs to expose the underlying content in a way that crawlers can discover.
A pagination interface that works perfectly for a human visitor can still create problems if subsequent pages depend entirely on JavaScript interactions or if the URLs are not independently accessible.
Pagination SEO: What Should a Healthy Implementation Look Like?
A useful pagination implementation generally has several characteristics.
Each Page Has a Distinct URL
Page 2 should have a URL that is different from page 1.
For example:
/products/
followed by:
/products/page/2/
or:
/products?page=2
The exact URL format can vary. What matters is that each page can be independently requested and identified.
Google recommends unique URLs for pages within paginated results. :contentReference[oaicite:6]{index=6}
Pagination Uses Crawlable Links
The HTML should expose navigation using normal anchor links when the goal is to allow crawlers to discover subsequent pages.
A basic pattern is:
<a href="/products/page/2/">Next</a>
rather than relying exclusively on a JavaScript event attached to a button.
Google specifically recommends linking paginated pages sequentially and using <a href> links so Googlebot can discover subsequent pages. :contentReference[oaicite:7]{index=7}
Paginated Pages Have Appropriate Canonicals
If page 2 is intended to exist as its own URL, its canonical should not automatically point back to page 1 simply because the pages belong to the same collection.
Review the canonical relationship carefully before making changes.
Avoid Fragment-Only Pagination
A structure such as:
/products/#page=2
does not provide the same URL-level separation as:
/products/page/2/
or:
/products?page=2
Google ignores URL fragments when crawling URLs, so fragment-only pagination can prevent the additional pages from being discovered as separate URLs. :contentReference[oaicite:8]{index=8}
Review JavaScript-Only Navigation
Load More and infinite-scroll interfaces can be useful for visitors, but the implementation should still provide a crawlable discovery path when additional pages or products need to be found by search engines.
A JavaScript interface is not automatically an SEO problem. The issue is whether important content remains discoverable and accessible through appropriate URLs.
Common Pagination SEO Problems
Page 2 Canonical Points to Page 1
This is one of the most important patterns to investigate.
If every pagination URL declares page 1 as canonical, the site’s canonical signals may not match the intended structure of the paginated collection.
Pagination Uses Only URL Fragments
If page numbers exist only after #, the crawler may not treat them as separate URLs.
Use real path or query-based URLs when separate paginated pages need to be discoverable.
Next Button Has No Crawlable URL
A button labelled “Next” may work through JavaScript while the initial HTML contains no useful <a href> navigation.
The browser experience can therefore look correct while crawler discovery is incomplete.
Paginated Pages Are Accidentally Noindexed
A noindex directive may be intentional in some architectures, but it should not be present accidentally on pages that are supposed to remain indexable.
Check both HTML meta robots and HTTP X-Robots-Tag directives.
Legacy rel=”next” / rel=”prev” Is Being Treated as the Main Solution
These annotations can still appear in older implementations, but Google no longer uses them for pagination.
They should not replace normal crawlable pagination links. :contentReference[oaicite:9]{index=9}
Pagination Depends Entirely on JavaScript
If the initial HTML contains only the first set of results and additional content appears only after a visitor clicks a control, inspect how the additional URLs and content are exposed.
For large collections, a crawlable URL structure can make discovery much clearer.
Pagination vs Load More vs Infinite Scroll
These are different user-experience patterns.
Traditional Pagination
Users move between separate pages using links.
Example:
1 2 3 4 Next
This naturally creates separate URLs when implemented correctly.
Load More
A visitor clicks a button to retrieve additional content.
This can provide a convenient experience, but the implementation should be evaluated to ensure important content and URLs remain discoverable.
Infinite Scroll
Additional content loads as the visitor scrolls.
This can create a smooth browsing experience, but the SEO implementation needs special attention because the browser interaction itself is not the same as crawler URL discovery.
Google’s guidance discusses all three patterns and emphasizes making sure crawlers can find the underlying content. :contentReference[oaicite:10]{index=10}
How to Use the Pagination SEO Checker
- Open the Pagination SEO Checker.
- Enter the URL of a page in a paginated sequence.
- Click Check Pagination SEO.
- Wait while PKCapra fetches the page.
- Review the overall diagnostic status.
- Examine the Pagination Signals table.
- Review detected Next, Previous, page-number and fragment URLs.
- Check the canonical URL.
- Review noindex signals.
- Investigate any red or yellow findings on the actual website.
For a thorough audit, test more than one page in the sequence. For example, check page 1, page 2, and a deeper page such as page 5 or page 10 when those URLs exist.
How to Fix Pagination SEO Problems
Start with the actual implementation rather than changing every signal automatically.
If Page 2 Canonicalizes to Page 1
Review whether page 2 is intended to be a distinct indexable URL.
If it is, investigate the canonical implementation so that it accurately represents the page.
If Pagination Uses Fragments
Replace fragment-only page navigation with independently addressable URLs when separate pagination pages need to be crawled and discovered.
If There Are No Crawlable Pagination Links
Expose the pagination sequence through normal anchor links with real destination URLs.
If Noindex Is Present
Determine why the noindex directive exists.
If it was intentional, document the reason. If it was accidental, correct the relevant meta robots or HTTP header configuration.
If Navigation Is JavaScript-Only
Review whether the important subsequent content has independently accessible URLs and whether those URLs can be discovered without requiring a user to click a JavaScript control.
Pagination SEO and Canonicalization Are Related but Not Identical
Pagination and canonicalization often appear together, but they solve different problems.
Pagination describes how a collection is divided and connected across multiple pages.
Canonicalization tells search engines which URL should represent a particular piece of content when multiple URLs are similar or duplicated.
A pagination page can therefore have a canonical relationship without being a duplicate of page 1.
If you are investigating a specific canonical problem, you can also use the URL Canonicalization Checker to inspect canonical relationships in more detail.
Pagination SEO and Crawl Efficiency
Large websites can have thousands or millions of URLs generated by categories, filters, sorting systems, search pages, pagination and other navigation mechanisms.
Pagination itself is not automatically a crawl-budget problem. The larger concern is whether a site’s URL architecture creates unnecessary or low-value URL variations that crawlers repeatedly need to process.
Google recommends minimizing unnecessary alternative URLs and designing URL structures that make crawling and indexing easier. :contentReference[oaicite:11]{index=11}
For broader crawl-efficiency diagnostics, use the Crawl Budget Analyzer alongside this checker.
Pagination and Indexability
A pagination page can be technically accessible but still contain an indexing directive that prevents it from being indexed.
That is why pagination should be reviewed together with indexability.
Use the Indexability Checker when you need a broader inspection of robots directives and indexability signals.
Pagination and Robots.txt
Robots.txt and pagination solve different problems.
Robots.txt can influence whether crawlers are allowed to fetch particular URL patterns, while pagination links determine how the crawler discovers subsequent pages.
If you are reviewing whether your site’s robots rules align with its pagination architecture, the Robots.txt Analyzer can provide an additional diagnostic layer.
Pagination and XML Sitemaps
A sitemap can help search engines discover important URLs, but it should not be treated as a replacement for a well-structured internal navigation system.
Pagination links, canonical URLs and sitemap URLs should make sense together.
For sitemap-specific diagnostics, explore the XML Sitemap Analyzer.
A Practical Pagination SEO Audit Workflow
For a real website, use this sequence:
Step 1: Identify the Pagination Pattern
Determine whether the site uses:
- Traditional pagination
- Query-parameter pagination
- Path-based pagination
- Load More
- Infinite scroll
- A combination of these methods
Step 2: Check Page 1
Confirm that the first page exposes appropriate links to subsequent pages.
Step 3: Check a Deeper Page
Test page 2 or another deeper page.
Look for:
- Unique URL
- Successful HTTP response
- Crawlable navigation
- Appropriate canonical
- Unexpected noindex
- Fragment-based URLs
Step 4: Compare the URLs
Make sure page 2, page 3 and other pages actually represent separate pages in the sequence.
Step 5: Review Canonicals
Do not assume that every page in a collection should canonicalize to page 1.
Check what the site’s actual content architecture requires.
Step 6: Investigate JavaScript
If navigation depends on Load More or infinite scroll, determine whether important content remains discoverable through crawlable URLs.
Step 7: Check the Wider Technical SEO Architecture
Use related PKCapra tools for:
- Indexability
- Canonicalization
- Robots.txt
- Crawl efficiency
- XML sitemaps
- Redirects
This produces a much more complete technical SEO picture than evaluating pagination in isolation.
What the Pagination SEO Checker Does Not Do
PKCapra’s Pagination SEO Checker is a diagnostic HTML and HTTP-response analyzer. It does not attempt to reproduce the entire Google crawling and indexing system.
It does not:
- Crawl your entire website
- Build a complete pagination map for every category
- Access Google Search Console
- Query Google’s index
- Determine whether Google has actually indexed a page
- Execute a full browser-based JavaScript rendering session
- Guarantee how Google will select a canonical
- Guarantee search rankings
- Replace server-log analysis
- Replace a full website crawl
The Load More and infinite-scroll detection is based on signals found in the fetched HTML and should therefore be treated as a diagnostic indication rather than a complete JavaScript rendering audit.
Privacy and Processing
The checker sends the URL you enter to the PKCapra server for analysis.
PKCapra fetches the target page, processes its HTTP response and HTML structure, and returns the diagnostic report to your browser.
The tool does not require you to upload a website database, Search Console export or server log.
Avoid submitting private, authenticated or sensitive URLs that you do not want the server to request.
Frequently Asked Questions
What is pagination SEO?
Pagination SEO is the practice of structuring multi-page collections so users and search engines can discover, navigate and understand the relationship between the pages.
Is pagination bad for SEO?
No. Pagination is a normal way to organize large collections. The important issue is whether the implementation provides accessible URLs, crawlable navigation and appropriate indexing and canonical signals.
Should page 2 have its own URL?
If page 2 is intended to be a distinct page in a pagination sequence, it should have a unique URL. Google specifically recommends unique URLs for paginated pages. :contentReference[oaicite:12]{index=12}
Should every pagination page canonicalize to page 1?
Not when the paginated pages are intended to exist as separate pages. Google recommends that each paginated page have its own canonical URL rather than using page 1 as the canonical for the entire sequence. :contentReference[oaicite:13]{index=13}
Does Google still use rel=”next” and rel=”prev”?
Google no longer uses these annotations for pagination. Other search engines may still use them. :contentReference[oaicite:14]{index=14}
Are URL fragments such as #page=2 good for SEO pagination?
They are not recommended when the goal is to create separate crawlable pagination URLs. Google ignores URL fragments when processing URLs for crawling. :contentReference[oaicite:15]{index=15}
Is Load More bad for SEO?
Not automatically. The important question is whether the additional content and URLs can be discovered and accessed appropriately without depending exclusively on user-triggered JavaScript interactions.
Can this tool tell me whether Google indexed page 2?
No. The tool analyzes the page’s HTTP and HTML signals. It does not access Google’s index or Search Console data.
Should I test only page 1?
For a meaningful pagination audit, test page 1 and at least one deeper page. If the site has a large collection, testing a deeper page can reveal problems that are not visible on the first page.
Use Pagination Diagnostics as Part of a Larger Technical SEO Audit
Pagination is one part of a website’s technical architecture.
A strong audit should consider pagination together with canonicalization, indexability, robots directives, redirects, XML sitemaps, internal linking and crawl efficiency.
PKCapra provides dedicated tools for these areas so you can investigate individual technical SEO signals without relying on one broad score.
Start with the Pagination SEO Checker, identify the specific signal that needs attention, and then use the relevant PKCapra diagnostic tool to investigate the underlying issue.