
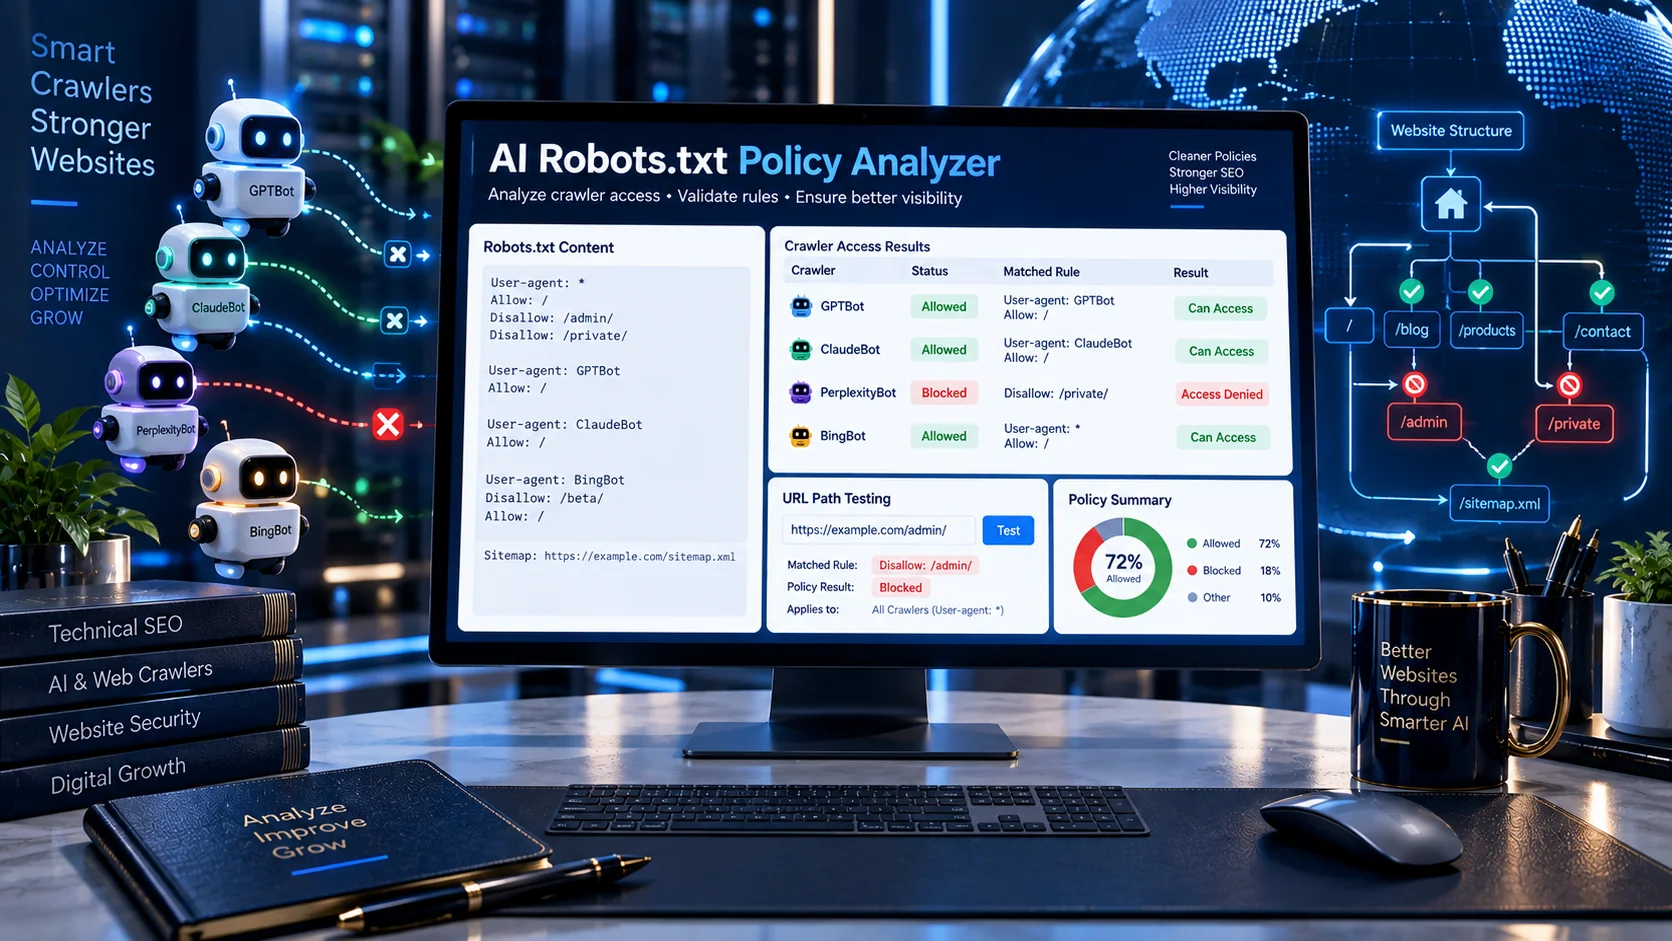
AI Robots.txt Policy Analyzer helps you understand how your website’s robots.txt file controls access for major AI crawlers. Instead of reading a long robots.txt file line by line, you can analyze crawler-specific rules, Allow and Disallow directives, wildcard patterns, conflicts, and the effective policy for a specific URL path.
As AI search and answer engines become more dependent on web crawling and retrieval, understanding crawler access rules is becoming an important part of technical SEO, AEO, and GEO. The Robots Exclusion Protocol defines User-agent, Allow, and Disallow rules for communicating crawler access preferences, while these rules are not themselves a form of access authorization.
AI Robots.txt Policy Analyzer
Analyze crawler-specific robots.txt rules, wildcard fallback, Allow/Disallow conflicts, and the effective policy seen by major AI crawlers.
Analyze AI Crawler Rules in Your Robots.txt
Enter your website URL and let PKCapra inspect the site’s robots.txt file.
The analyzer identifies policies for major AI crawler user agents, including:
- OAI-SearchBot
- GPTBot
- Claude-SearchBot
- ClaudeBot
- PerplexityBot
- Google-Extended
You can review each crawler’s applicable rules and understand whether a particular path is allowed, blocked, or affected by a more specific directive.
What the AI Robots.txt Policy Analyzer Checks
Crawler-Specific User-Agent Rules
A robots.txt file can contain separate groups for different crawlers. A specific AI crawler may have its own rules, while other crawlers may fall back to the wildcard User-agent: * group when no matching crawler-specific group exists.
The analyzer separates these policies so you can see which rules apply to each supported AI crawler.
Allow and Disallow Directives
Allow and Disallow directives determine whether a matching URL path is permitted or restricted under the applicable robots.txt policy.
For example, a website might allow an AI crawler to access /articles/ while blocking /private/. The analyzer makes these directives easier to inspect without manually interpreting the complete robots.txt file.
Wildcard Rules
Robots.txt supports wildcard patterns such as *, which can match multiple characters or URL patterns. The $ character can be used to indicate the end of a matching pattern.
The analyzer identifies these patterns and evaluates them when determining the effective policy for a requested path.
Rule Conflicts
A robots.txt file can contain overlapping Allow and Disallow directives.
For example, a broad rule may block /private/ while a more specific Allow rule permits /private/public-page/.
The effective result depends on the applicable matching rules and their specificity. The Robots Exclusion Protocol specifies that the most specific matching rule should be used, while Google documents the longest matching rule and least restrictive result for conflicting rules in its crawler implementation.
Effective Policy for a Specific Path
The most useful part of the analyzer is the ability to evaluate a particular website path.
Instead of only showing:
Disallow: /
the analyzer can determine what that rule means for a path such as:
/blog/
or:
/products/example-product/
This makes it easier to identify whether an important page or section is accessible to a particular AI crawler.
Why AI Robots.txt Policies Matter for GEO
Generative Engine Optimization is not limited to writing content. Before publicly accessible content can potentially be retrieved by an automated system, the system must be able to access the relevant resources.
A crawler-specific robots.txt restriction can therefore affect the technical accessibility of website sections for that crawler.
This does not mean that allowing a crawler guarantees AI visibility, citations, rankings, or inclusion in generated answers. Robots.txt primarily communicates crawling preferences; it does not guarantee that a crawler will retrieve, index, cite, or use a page. The official Robots Exclusion Protocol explicitly states that robots.txt rules are not access authorization.
How to Use the AI Robots.txt Policy Analyzer
1. Enter Your Website URL
Enter the public URL of the website whose robots.txt policy you want to inspect.
2. Review AI Crawler Policies
The analyzer retrieves the site’s robots.txt file and identifies relevant rules for the supported AI crawlers.
3. Select a Crawler and Path
Review the policy for a specific crawler and, where applicable, test a website path such as /, /blog/, /products/, or another public URL path.
4. Examine the Effective Rule
The results show the relevant Allow or Disallow policy and help identify the rule responsible for the final result.
5. Investigate Conflicts
If a broad rule and a more specific rule overlap, review the reported matching rules before changing your robots.txt configuration.
How to Read the Results
An Allowed result means the applicable robots.txt rules do not disallow the tested path for that crawler.
A Blocked result means the applicable policy contains a matching restriction for that crawler and path.
A Wildcard result indicates that the crawler is being evaluated under the general User-agent: * policy rather than a dedicated crawler group.
A Specific Rule result indicates that the crawler has a dedicated user-agent group that applies to it.
When multiple rules match the same URL, the analyzer considers rule specificity when determining the effective policy.
AI Crawler Access Is Not the Same as Crawler Identity
A robots.txt file works with declared crawler user-agent identifiers. A matching user-agent string does not independently prove that a request actually came from the claimed crawler.
This distinction is important when interpreting AI crawler traffic, security logs, or server requests. Robots.txt should be treated as a crawler policy mechanism rather than an authentication system.
Robots.txt and Sitemap Rules Work Together
A robots.txt file can also contain Sitemap: declarations that identify XML sitemap locations. Google documents the Sitemap directive as a way to indicate where a site’s sitemap is located, while sitemap discovery and crawler permissions remain separate concepts.
If you are investigating AI crawl coverage, use the XML Sitemap Analyzer alongside this tool to examine your sitemap structure and URLs.
For broader crawl diagnostics, the Indexability / Crawlability Analyzer can help investigate additional crawl and indexability signals.
You can also use the Internal Links & Crawl Path Analyzer to examine how your important pages are connected internally.
Important Limitations
Robots.txt is only one part of a website’s technical access environment.
CDN configuration, web application firewalls, server rules, authentication, rate limiting, redirects, HTTP errors, network restrictions, and other controls can affect actual access to a URL.
The analyzer therefore evaluates the robots.txt policy rather than guaranteeing that a real crawler will successfully retrieve a page.
Changes to robots.txt should also be reviewed carefully because broad rules can affect multiple crawlers and URL sections at once.
Privacy and Processing
The analyzer works with publicly accessible website URLs and the robots.txt information required to perform the analysis.
You do not need to upload your website files or provide WordPress administrator access.
Avoid entering private or authenticated URLs into a public website analysis tool.
Frequently Asked Questions
What is an AI Robots.txt Policy Analyzer?
An AI Robots.txt Policy Analyzer examines a website’s robots.txt file and explains how its Allow and Disallow rules apply to major AI crawlers.
Which AI crawlers can I analyze?
PKCapra currently supports OAI-SearchBot, GPTBot, Claude-SearchBot, ClaudeBot, PerplexityBot, and Google-Extended.
What does User-agent: * mean?
User-agent: * is a wildcard group that can apply to crawlers that do not have a more specific matching user-agent group, subject to the crawler’s implementation.
What is the difference between Allow and Disallow?
Disallow tells a compliant crawler not to access matching paths, while Allow permits matching paths and can be used to create more specific exceptions within a broader restriction.
What happens when Allow and Disallow rules conflict?
The applicable result depends on which rules match and their specificity. The Robots Exclusion Protocol specifies using the most specific matching rule, while Google’s documented interpretation uses the longest matching path and the least restrictive result when conflicting rules are otherwise equivalent.
Does robots.txt block access to my website?
Robots.txt communicates crawling preferences to compliant crawlers. It is not an authentication or security mechanism and should not be used as a replacement for access controls.
Does allowing an AI crawler guarantee AI visibility?
No. Allowing a crawler through robots.txt does not guarantee crawling, indexing, retrieval, citation, ranking, or inclusion in AI-generated answers.
Can I use this tool to check a specific page?
Yes. Testing a specific path helps you understand which robots.txt rule applies to an individual section or URL instead of only reviewing the overall robots.txt configuration.